AI · alternatives · 2026

24 alternatives to Exla FLOPs
On-Demand GPU clusters - The Cheapest H100s Anywhere
Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes. Prices are shown for the 2 we have checked on their own sites, 2 of them free or with a free tier.
- 1GC
Hi HN, YC w24 company here. We just pivoted from drone delivery to build gpudeploy.com, a website that routes on-demand traffic for GPU instances to idle compute resources. The experience is similar to lambda labs, which we’ve really enjoyed for training our robotics models, but their GPUs are never available for on-demand. We are also trying to make it more no-nonsense (no hidden fees, no H100 behind “contact sales”, etc.). The tech to make this work is actually kind of nifty, we may do an in-depth HN post on that soon. Right now, we have H100s, a few RTX 4090s and a GTX 1080 Ti online.…
2024 · gpudeploy.com · its alternatives →
- 2

Affordable H100, H200, GB300, and B200 GPU compute for training, inference, and everything in between.
Sep 2026 · compute.cheap · its alternatives →
- 3SF
Hey folks! We're Alex and Evan, and we're working on putting together a 512 H100 compute cluster for startups and researchers to train large generative models on. - it runs at the lowest possible margins (<$2.00/hr per H100) - designed for bursty training runs, so you can take say 128 H100s for a week - you don’t need to commit to multiple years of compute or pay for a year upfront Big labs like OpenAI and Deepmind have big clusters that support this kind of bursty allocation for their researchers, but startups so far have had to get very small clusters on very long term contracts, wait…
2023 · sfcompute.org · its alternatives →
- 4

The video demo runs a 7b Model on a normal gaming GPU. I think it already works quite well (accounting for the limited hardware power). :)
2024 · github.com · its alternatives →
- 5

Hi everyone, I'm kinda involved in some retrogaming and with some experiments I ran into the following question: "It would be possible to run transformer models bypassing the cpu/ram, connecting the gpu to the nvme?" This is the result of that question itself and some weekend vibecoding (it has the linked library repository in the readme as well), it seems to work, even on consumer gpus, it should work better on professional ones tho
Feb 2026 · github.com · its alternatives →
- 6

Hi HN! I'm just sharing a project I've been working on during the LLM Efficiency Challenge - you can now finetune Llama with QLoRA 5x faster than Huggingface's original implementation on your own local GPU. Some highlights: 1. Manual autograd engine - hand derived backprop steps. 2. QLoRA / LoRA 80% faster, 50% less memory. 3. All kernels written in OpenAI's Triton language. 4. 0% loss in accuracy - no approximation methods - all exact. 5. No change of hardware necessary. Supports NVIDIA GPUs since 2018+. CUDA 7.5+. 6. Flash Attention support via Xformers. 7. Supports 4bit and 16bit…
2023 · github.com · its alternatives →
- 7
 Computable GPU Index (CGI)free▲444
Hey we are Computable. We spent years building trading infrastructure at Jump Trading and Coinbase. From that point of view, compute looks like energy markets before 2000: everything trades through private bilateral leases, there’s no visible price, and nothing can be resold. The same H100 rents at a 2x spread depending on who’s asking, and once you sign a 24-month lease, it can never change hands. So we built a market for GPU nodes, sold by the calendar week. Here are three things you can do on it that you can’t do anywhere else: - Buy exactly the weeks you need. Three nodes for the last…
Aug 2026 · getcomputable.com · its alternatives →
- 8

Hi HN, We’ve launched a GPU cloud platform offering on-demand access to high-end GPUs — with pricing starting at $0.79/hr, no queue, and no preemption. What we offer: - On-demand H100, H200, and B200 instances - H200 pricing from $0.79/hr - Multi-region support: US, Singapore, and Europe - No queuing, no bidding, and no interruptions - Used by AI startups, researchers, and open-source developers Try it: https://hpc-ai.com/?utm_source=hackernews&utm_medium=post&ut... We built this after facing our own frustrations with high prices and long wait times on other…
2025 · hpc-ai.com · its alternatives →
- 9

Self-host AI/ML with the world's cheapest GPU cloud
2025 · thundercompute.com · its alternatives →
- 10

Find the cheapest GPUs (H100s starting at $1.65/hr)
2024 · app.primeintellect.ai · its alternatives →
- 11

Greetings HN! This is Doruk from Oblivus, and I'm excited to announce the launch of our platform, Oblivus Cloud. After more than a year of beta testing, we're excited to offer you a platform where you can deploy affordable and scalable GPU virtual machines in as little as 30 seconds! https://oblivus.com/cloud - What sets Oblivus Cloud apart? At the start of our journey, we had two primary goals in mind: to democratize High-Performance Computing and make it as straightforward as possible. We understand that maintaining GPU servers through major cloud service providers can be…
2023 · oblivus.com · its alternatives →
- 12
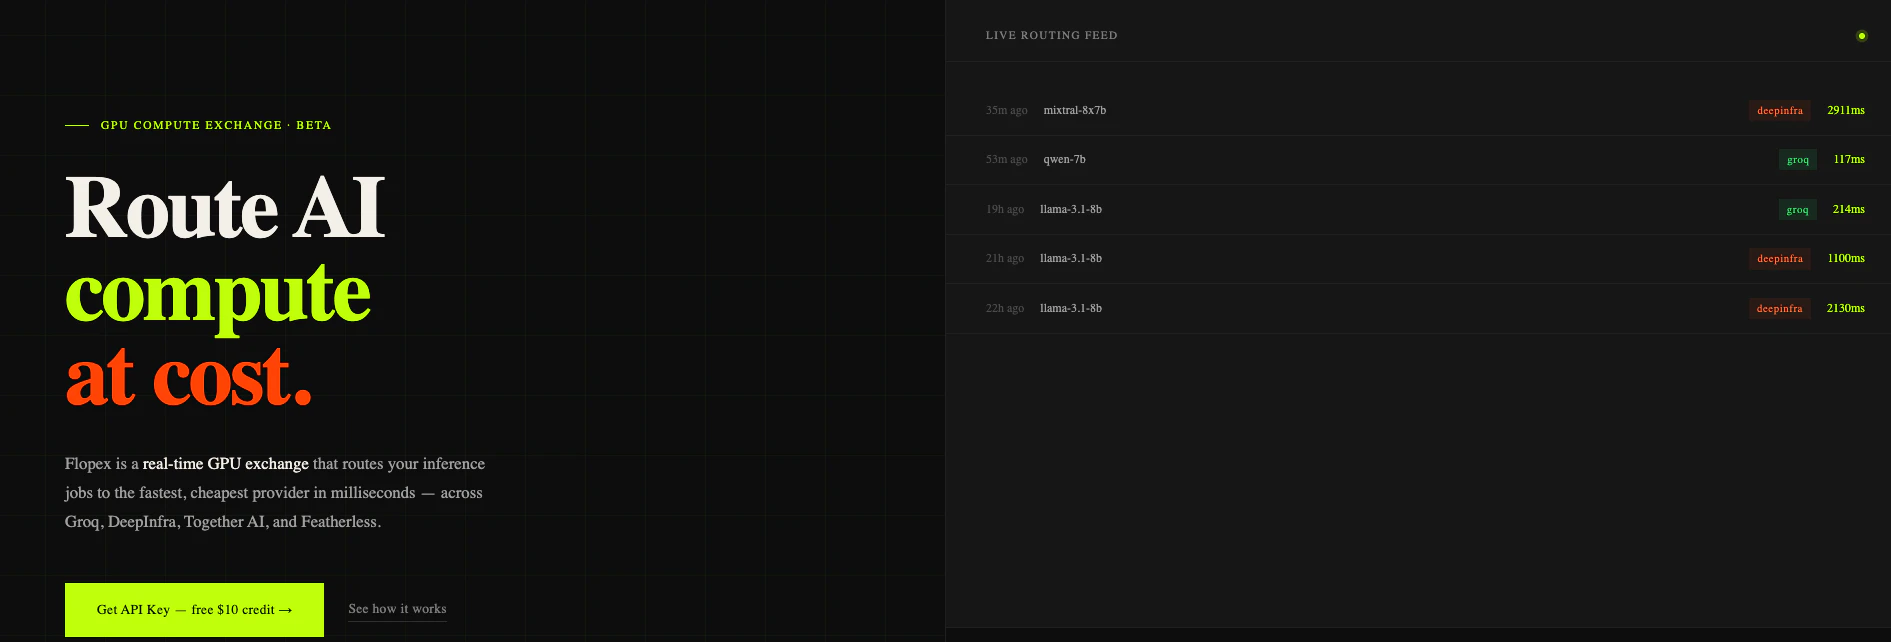 Flopex▲2
Your AI provider will hit capacity. Your product won't.
Apr 2026 · flopex.ai · its alternatives →
- 13TC
Hello HN! I’m Jonathan from TensorDock. After 7 months in beta, we’re finally launching Core Cloud, our platform to deploy GPU virtual machines in as little as 45 seconds! https://www.tensordock.com/product-core Why? Training machine learning workloads at large clouds can be extremely expensive. This left us wondering, “how did cloud ever become more expensive than on-prem?” I’ve seen too many ML startups buy their own hardware. Cheaper dedicated servers with NVIDIA GPUs are not too hard to find, but they lack the functionality and scalability of the big clouds. We thought to…
2022 · tensordock.com · its alternatives →
- 14
- 15

Hey HN, we wanted to share our repo where we fine-tuned Llama 3.1 on Google TPUs. We’re building AI infra to fine-tune and serve LLMs on non-NVIDIA GPUs (TPUs, Trainium, AMD GPUs). The problem: Right now, 90% of LLM workloads run on NVIDIA GPUs, but there are equally powerful and more cost-effective alternatives out there. For example, training and serving Llama 3.1 on Google TPUs is about 30% cheaper than NVIDIA GPUs. But developer tooling for non-NVIDIA chipsets is lacking. We felt this pain ourselves. We initially tried using PyTorch XLA to train Llama 3.1 on TPUs, but it was rough: xla…
2024 · github.com · its alternatives →
- 16

Simple scheduler for running jobs on GPUs. Contribute to ExpectationMax/simple_gpu_scheduler development by creating an account on GitHub.
2019 · github.com · its alternatives →
- 17AG
We built, saga[1] a layer that lets smaller teams access enterprise GPU discounts through collective buying power. How it works: 1. Aggregate GPU spend across hundreds of ML teams 2. Get enterprise rates through combined volume 3. Pass savings to users, monetize via provider partnerships Technical notes: - Works at billing layer only (no access to code/data) - Supports existing cloud setups or managed GPUs - Private beta running since January, opening more spots for March - Currently seeing ~50% savings on H100s/A100s [1] https://trysaga.ai
2025 · trysaga.ai · its alternatives →
- 18

Hi HN, we are Ed, Zach, and Ronald, creators of Shadeform (https://www.shadeform.ai/), a GPU marketplace to see live availability and prices across the GPU market, as well as to deploy and reserve on-demand instances. We have aggregated 8+ GPU providers into a single platform and API, so you can easily provision instances like A100s and H100s where they are available. From our experience working at AWS and Azure, we believe that cloud could evolve from all-encompassing hyperscalers (AWS, Azure, GCP) to specialized clouds for high-performance use cases. After the launch of…
2023 · shadeform.ai · its alternatives →
- 19

Howdy! Keeping with the trend of being influenced by https://diskprices.com, I wanted to make a resource for GPUs on eBay that also take into account a performance metric I tend to look at when checking GPUs. It's still a work in progress, but it's at a state where I think some of HN might find it useful! There are a few things that I have planned to add in the coming day(s): 1. Filters for compatible slots and connectors 2. Expand for different eBay regions, rather than just US focus Let me know if you have any questions or want more / different filters on the page or if I…
2024 · gpupricecompare.com · its alternatives →
- 20
 crunr ▲106
Launch and run any compute job on AWS with 1 command
May 2026 · crunr.com · its alternatives →
- 21

Contribute to Mega4alik/ollm development by creating an account on GitHub.
2025 · github.com · its alternatives →
- 22GP
Out of curiosity, I put together a simple website which tracks the prices for a few variations of A100/H100 GPUs by hour broken out between spot/ondemand, form factor and provider. Specifically I was tailoring the tool towards the smaller, emerging providers like runpod, gpulist.ai, lambda labs etc. Anyone have any ideas to expand/refine it?
2024 · computeindex.michaelgiba.com · its alternatives →
- 23TG
Hey folks! I’m Jonathan from TensorDock, and we’re building a cloud GPU marketplace. We want to make GPUs truly affordable and accessible. I once started a web hosting service on self-hosted servers in middle school. But building servers isn’t the same as selling cloud. There’s a lot of open source software to manage your homelab for side projects, but there isn’t anything to commercialize that. Large cloud providers charge obscene prices — so much so that they can often pay back their hardware in under 6 months with 24x7 utilization. We are building the software that allows anyone to become…
2024 · dashboard.tensordock.com · its alternatives →
- 24

Manage your GPUs across NVIDIA, AMD, Intel, and Apple Silicon systems. - treadiehq/gpu-kill
2025 · github.com · its alternatives →
Also compare
- gpudeploy.com – "Airbnb" for GPUs alternatives
- The cheapest GPU cloud – H100s at $2.04/HR, H200s at $3/HR alternatives
- San Francisco Compute – 512 H100s at <$2/hr for research and startups alternatives
- I've built a locally running Perplexity clone alternatives
- Llama 3.1 70B on a single RTX 3090 via NVMe-to-GPU bypassing the CPU alternatives
- 80% faster, 50% less memory, 0% loss of accuracy Llama finetuning alternatives
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →