Dev tools · alternatives · 2026
24 alternatives to Pduut
From textbooks to structured knowledge — PDFs, untangled
Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes.
- 1
 PDF Dino▲155
Extract structured tables from messy PDFs using AI. Export to Excel, CSV, or JSON. Try 20 pages free—no credit card needed.
2025 · pdfdino.com · its alternatives →
- 2

Documind is an open-source tool that turns documents into structured data using AI. What it does: - Extracts specific data from PDFs based on your custom schema - Returns clean, structured JSON that's ready to use - Works with just a PDF link + your schema definition Just run npm install documind to get started.
2024 · github.com · its alternatives →
- 3

The PDF parser is a rule based parser which uses text co-ordinates (boundary box), graphics and font data. The PDF parser works off text layer and also offers a OCR option to automatically use OCR if there are scanned pages in your PDFs. The OCR feature is based off a modified version of tika which uses tesseract underneath. The PDF Parser offers the following features: * Sections and subsections along with their levels. * Paragraphs - combines lines. * Links between sections and paragraphs. * Tables along with the section the tables are found in. * Lists and nested lists. * Join content…
2024 · github.com · its alternatives →
- 4
 Koncile ▲251
Customisable OCR for all your data extraction needs
2024 · koncile.ai · its alternatives →
- 5

Hey HN, we’re Adi and Arnav. A few months ago, we hit a wall trying to get LLMs to answer questions over research papers and instruction manuals. Everything worked fine, until the answer lived inside an image or diagram embedded in the PDF. Even GPT‑4o flubbed it (we recently tried O3 with the same, and surprisingly it flubbed it too). Naive RAG pipelines just pulled in some text chunks and ignored the rest. We took an invention disclosure PDF (https://drive.google.com/file/d/1ySzQgbNZkC5dPLtE3pnnVL2rW_9...) containing an IRR‑vs‑frequency graph and asked GPT “From…
2025 · github.com · its alternatives →
- 6

Hi HackerNews, Lately, I have seen an explosion in posts offering paid APIs/services to get unstructured data into LLMs (i.e. langchain extract, ragflow, unstructured, unstract, just to name a few) and I have been largely disappointed by them, either because they fail to implement multimodal support, fail to give good context for "really tricky" PDFs / Word docs / Powerpoints, or are just plain difficult to use. In light of all these posts I figured I'd share my solution that has been working smoothly for me and my clients. I put it up on GitHub for free so you can check it…
2024 · github.com · its alternatives →
- 7
- 8

- 9

Extract structured data from unstructured documents with AI
2025 · app.unstructure.ai · its alternatives →
- 10
- 11

Advanced PDF Search Tool | Bulk PDF Search
2025 · digitaljomon.gumroad.com · its alternatives →
- 12
- 13
Hello HN, I built Parseflow, it's a simple, evidence focused extraction API which can extract take PDFs, DOCX and TXT files and extract/chunk the info inside them to improve LLM context and reduce token usage. If you want to try out a demo, you can find it here: demo.parseflow.tech I am still a student dev, graduating high school this year so I still have a lot to learn. I am trying to build this project to help pay for tuition this year but also to help me learn. So any feedback, advice, questions, etc... are super appreciated and either I will try to respond to the comments or you can…
May 2026 · docs.parseflow.tech · its alternatives →
- 14

Merge, rearrange, and organize documents, completely offline
Nov 2025 · pdf-stitch.ogwenya.dev · its alternatives →
- 15

Hey HN, solo dev here. After years of frustration with how LLMs handle complex documents, especially PDFs with tables, I decided to build a solution myself. My approach uses a Markdown conversion step to preserve the table structure, which seems to work surprisingly well for chunking. This little parser is the first public piece of a much larger, privacy-focused AI platform I'm building. I'm pretty much running on fumes financially, so any feedback, critique, or support is massively appreciated. Happy to answer any questions about the approach!
Nov 2025 · github.com · its alternatives →
- 16

Chat PDF and summarize documents using powerful GPT4 AI. With the help of ChatPDF you can build custom chatbot trained on your pdf and do question answering over your PDF documents.
2023 · documind.chat · its alternatives →
- 17

Hi HN! I built Docuglean, an open-source SDK for intelligent document processing that works with OpenAI, Mistral, Google Gemini, and Hugging Face models. The idea came from repeatedly writing boilerplate code to extract structured data from invoices, receipts, and other documents. Instead of wrestling with different API formats, I wanted a unified interface that: - Extracts structured data using Zod/Pydantic schemas - Classifies and splits multi-section documents (e.g., medical records) - Processes documents in batches with automatic error handling - Works locally without APIs (for…
Nov 2025 · github.com · its alternatives →
- 18
Batch extract structured data from unstructured sources.
2025 · extractany.com · its alternatives →
- 19
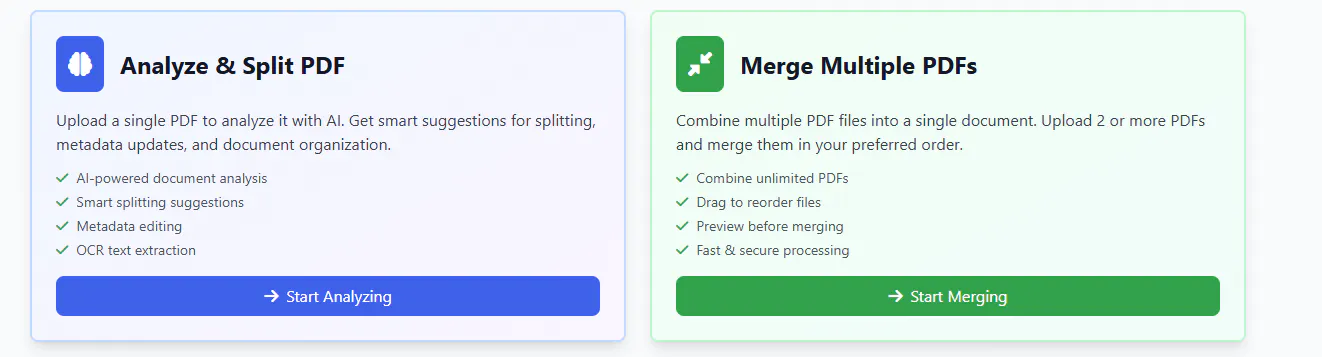
AI-powered PDF tool with GPT-4, split analyze and merge PDFS
Oct 2025 · pdfsmart.replit.app · its alternatives →
- 20

We're excited to release PaperQA2, an open source RAG library specialized to work with the scientific literature. We've seen some really compelling results with it (https://paper.wikicrow.ai), like superhuman performance at question answering and summarization when compared with expert scientists. PaperQA2 is a major overhaul of our prior PaperQA system, it includes automatically obtained rich metadata for each paper, a CLI to work with local papers directly, a local full-text search engine for keywords searches over PDF files, a state-of-the-art algorithm for LLM-based re-ranking…
2024 · github.com · its alternatives →
- 21

A Python library to inspect and modify the internal structure of a PDF file - desgeeko/pdfsyntax
2021 · github.com · its alternatives →
- 22

Most products that touch PDFs or images quietly rebuild the same thing: a hacked-together “router” that picks which OCR/vision API to call, normalizes the responses, and prays the bill is sane at the end of the month. DocsRouter is that layer as a product: one stable API that talks to multiple OCR engines and vision LLMs, lets you route per document based on cost/quality/latency, and gives you normalized outputs (text, tables, fields) so your app doesn’t care which provider was used. It’s meant for teams doing serious stuff with documents: invoices/receipts, contracts,…
Dec 2025 · docsrouter.com · its alternatives →
- 23

A modern online PDF toolkit with zero friction
Nov 2025 · mypdftools.xyz · its alternatives →
- 24
Also compare
- PDF Dino alternatives
- Documind – Open-source AI tool to turn documents into structured data alternatives
- Open-source Rule-based PDF parser for RAG alternatives
- Koncile alternatives
- Morphik – Open-source RAG that understands PDF images, runs locally alternatives
- I just open sourced my document/website extractor for Vision-LLMs alternatives
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →