Life & fun · alternatives · 2026
24 alternatives to Wikipedia2Vec – A tool for learning embeddings of words and entities
Wikipedia2Vec is a tool that learns embeddings of words and entities from Wikipedia data. Launched in 2018, it converts Wikipedia's text and structural information into numerical representations that capture semantic… Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes. Prices are shown for the 1 we have checked on their own sites, 1 of them free or with a free tier. Wikipedia2Vec – A tool for learning embeddings of words and entities launched in 2018; newer entries below may have overtaken it.
- 1SM
2016 · sense2vec.spacy.io · its alternatives →
- 2

- 3

Here's a small demonstration of the fundamental aspects of the word-to-vec algorithm. It's implemented in a single python script and depends only on a single text file for training. It's not meant to be blazingly fast or anything, just a toy example to aid my understanding of how word vectors might be learnt from a corpus.
2023 · github.com · its alternatives →
- 4

We’ve recently open-sourced Model2vec, a method to distill sentence transformers into static embeddings that outperform all previous approaches by a large margin on MTEB. Our new models set a new state-of-the-art for static embeddings. Main features: - Our best model (potion-base-8M) has only 8M parameters, which is ~30mb on disk - Inference is ~500x faster than the distilled base model (bge-base), on a CPU - New models can be distilled in 30 seconds on a CPU without requiring a dataset - just a vocabulary - Numpy-only inference: The packaged can be install the package with minimal…
2024 · github.com · its alternatives →
- 5

Hey HN! We’ve just open-sourced model2vec-rs, a Rust crate for loading and running Model2Vec static embedding models with zero Python dependency. This allows you to embed text at (very) high throughput; for example, in a Rust-based microservice or CLI tool. This can be used for semantic search, retrieval, RAG, or any other text embedding usecase. Main Features: - Rust-native inference: Load any Model2Vec model from Hugging Face or your local path with StaticModel::from_pretrained(...). - Tiny footprint: The crate itself is only ~1.7 mb, with embedding models between 7 and 30 mb. Performance:…
2025 · github.com · its alternatives →
- 6
 Google EmbeddingGemma 2free▲318
An open, lightweight multimodal embedding model
18d ago · blog.google · its alternatives →
- 7AL
Hi HN! I am Maria, solo founder of DataQA (https://dataqa.ai/), a tool to search and label documents for various NLP tasks (e.g. entity extraction, entity linking, etc). I have worked as a data scientist and ML engineer for the better part of a decade, and over that time have specialised mainly in applications involving natural language processing (NLP). One of the key questions I have always had at the back of my mind is whether my time was well spent. Whenever I spent more time on feature engineering or trying different models, I always wondered whether I would get better…
2021 · its alternatives →
- 8

I've been playing with embeddings and wanted to try out what results the embedding layer will produce based on just word-by-word input and addition / subtraction, beyond what many videos / papers mention (like the obvious king-man+woman=queen). So I built something that doesn't just give the first answer, but ranks the matches based on distance / cosine symmetry. I polished it a bit so that others can try it out, too. For now, I only have nouns (and some proper nouns) in the dataset, and pick the most common interpretation among the homographs. Also, it's case sensitive.
2025 · calc.datova.ai · its alternatives →
- 9

- 10

A parallel implementation of "graph2vec: Learning Distributed Representations of Graphs" (MLGWorkshop 2017). - benedekrozemberczki/graph2vec
2019 · github.com · its alternatives →
- 11AG
A daily visual guessing game drawn from this day in Wikipedia history.
2022 · doodleai.darraghoriordan.com · its alternatives →
- 12

The Virtual Feature Store. Turn your existing data infrastructure into a feature store. - featureform/featureform
2021 · github.com · its alternatives →
- 13

After working with LLMs for long enough, I found myself wanting a lightweight utility for doing various small tasks to prepare inputs, locate information and create evaluators. This library is two things: a very simple model and utilities that inference it (eg. fuzzy deduplication). The target platform is CPU, and it’s intended to be light, fast and pip installable — a library that lowers the barrier to working with strings semantically. You don’t need to install pytorch to use it, or any deep learning runtimes. How can this be accomplished? The model is simply token embeddings that are…
2024 · github.com · its alternatives →
- 14

Much improved new version. Search for words similar to the query. For example, "death" will find "death", "dying", "dead", "killing"... Incredibly useful for exploring large text datasets where exact matches are too restrictive.
2024 · github.com · its alternatives →
- 15
 Wikiwand▲169
Streamline Wikipedia knowledge and answer your questions
2024 · wikiwand.com · its alternatives →
- 16

Intuitive Annotation Tool for Information Extraction / Named Entity Recognition using localturk / Amazon Mechanical Turk - Varal7/ieturk
2018 · github.com · its alternatives →
- 17TA
2022 · observablehq.com · its alternatives →
- 18IM
As a grad student (and an ADHDer), I had trouble doing literature review systematically. To combat this, I made a website that finds similar papers using the meaning of the thing I am looking for. I used MixedBread's [^1] embedding model to generate vectors from the abstracts. I store and search similar vectors using Milvus [^2] and finally use Gradio [^3] to serve the frontend. I update the vector database weekly by pulling the metadata dataset from Kaggle [^4]. To speed up the search process on my free oracle instance, I binarise the embeddings and use Hamming distance as a metric. I would…
2024 · papermatch.mitanshu.tech · its alternatives →
- 19

Google's first natively multimodal embedding model
Mar 2026 · blog.google · its alternatives →
- 20
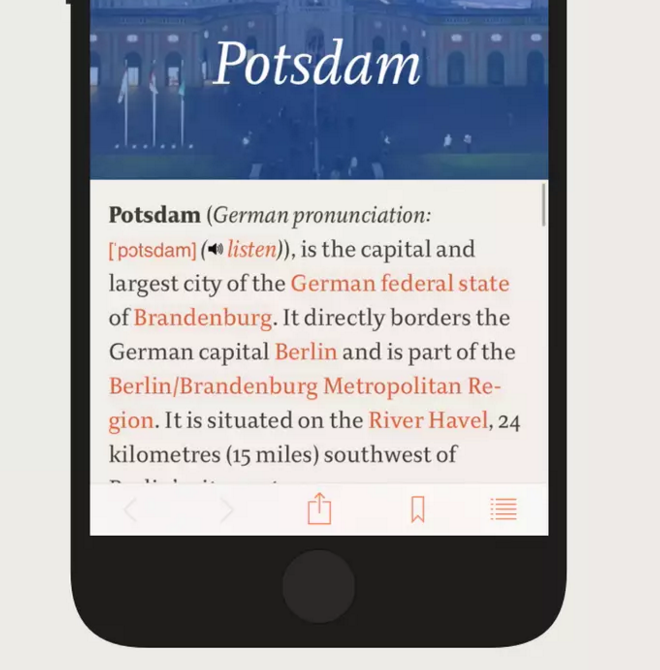 V for Wiki 1.0▲134
A beautifully designed Wikipedia app for iOS
2016 · ohiocollegefootball.com · its alternatives →
- 21SC
2024 · app.airtrain.ai · its alternatives →
- 22

Summon holy compute. Sacred Infrastructure, Developer-Native.
2018 · basilica.ai · its alternatives →
- 23GO
Small experiment of visualization of wikipedia articles as a graph using d3.js.<p>Articles with more traffic are bigger. I computed the semantic similarity using LSI with python (gensim) You have to scroll down/right a bit!<p>http://similarityapi.appspot.com/graph/?title=blade%20runner<p>There is also a JSON api: http://similarityapi.appspot.com/api/v1/?limit=100&title=blade%20runner<p>All feedback is appreciated:<p>@lucamartinetti [email protected]
2012 · similarityapi.appspot.com · its alternatives →
- 24

Using word vectors to classify spam messages. Contribute to doodyparizada/word2vec-spam-filter development by creating an account on GitHub.
2017 · github.com · its alternatives →
Also compare
- Sense2vec model trained on all 2015 Reddit comments alternatives
- Wiki2Map alternatives
- Word2vec Algorithm in ~100sloc with NumPy alternatives
- Model2vec – Lightning-fast Static Embeddings for RAG/Semantic Search alternatives
- Model2vec-Rs – Fast Static Text Embeddings in Rust alternatives
- Google EmbeddingGemma 2 alternatives
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →