AI · alternatives · 2026
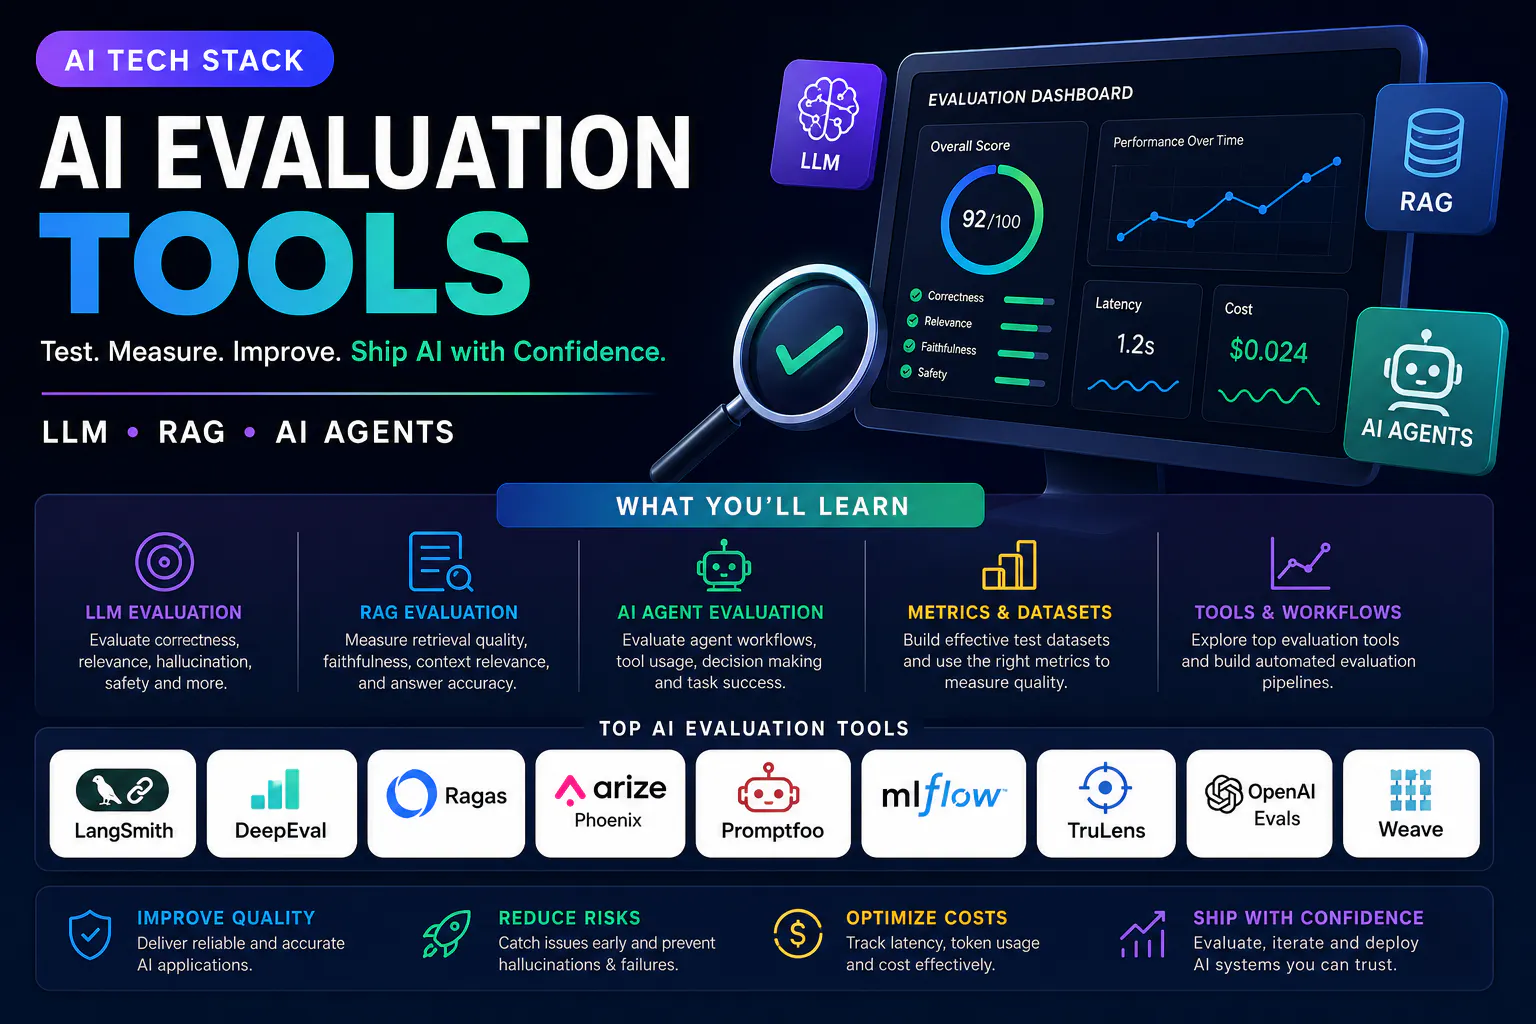
24 alternatives to AI Evaluation Tools
Test LLMs, RAG & AI Agents with Confidence
Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes.
- 1
 LLMWare▲358
Dev tool to make AI apps to deploy privately or locally
2024 · llmware.ai · its alternatives →
- 2
- 3
 Promptology▲232
AI prompt engineering business model guide
2023 · shushantlakhyani.gumroad.com · its alternatives →
- 4

I built this tool because I wanted a way to just take a bunch of URLs or domains, and query their content in RAG applications. It takes away the pain of crawling, extracting content, chunking, vectorizing, and updating periodically. I'm curious to see if it can be useful to others. I meant to launch this six months ago but life got in the way...
2024 · embedding.io · its alternatives →
- 5
 RagMetrics▲13
We built live AI evaluation to detect hallucinations, grounding issues, and drift as outputs are generated. This helps teams move GenAI from pilots into production.
2025 · ragmetrics.ai · its alternatives →
- 6
 Deepmark AI▲97
LLM benchmarking tool for task-specific metrics on your data
2023 · github.com · its alternatives →
- 7

- 8

Ragas is an open-source library for evaluating and testing RAG and other LLM applications. Github: https://docs.ragas.io/en/stable/, docs: https://docs.ragas.io/. Ragas provides you with different sets of metrics and methods like synthetic test data generation to help you evaluate your RAG applications. Ragas started off by scratching our own itch for evaluating our RAG chatbots last year. Problems Ragas can solve - How do you choose the best components for your RAG, such as the retriever, reranker, and LLM? - How do you formulate a test dataset…
2024 · github.com · its alternatives →
- 9AF
We’ve built an AI risk assessment tool designed specifically for GenAI/LLM applications. It's still early, but we’d love your feedback. Here’s what it does: 1. it performs comprehensive AI risk assessments by analyzing your codebase against different AI regulation/framework or even internal policies. It identifies potential issues and suggests fixes directly through one click PRs. 2. the first framework the platform supports is OWASP Top 10 for LLM Applications 2025, upcoming framework will be ISO 42001 as well as custom policy documents. 3. we're a small, early stage team, so the…
2025 · gettavo.com · its alternatives →
- 10

🐢 Open-Source Evaluation & Testing library for LLM Agents - Giskard-AI/giskard-oss
2024 · github.com · its alternatives →
- 11

- 12

- 13

- 14

I have been working in AI space for a while now, first at FAANG with ML since 2021, then with LLM in start-ups since early 2023. I think LLM Application development is extremely iterative, more so than any other types of development. This is because to improve an LLM application performance (accuracy, hallucinations, latency, cost), you need to try various combinations of LLM models, prompt templates (e.g., few-shot, chain-of-thought), prompt context with different RAG architecture, different agent architecture, and more. There are thousands of possible combinations and you need a process…
2024 · github.com · its alternatives →
- 15
 Trails▲81
Hey all, Justin here. I previously built Phind, the AI search engine for developers. One of the biggest problems we had there was figuring out what went wrong with bad searches. We had tons of searches per day, but less than 1% of users gave any explicit feedback. So we were either manually digging through searches or making general system improvements and hoping they helped. This problem gets harder with agents. Traces are longer and more complex. It takes more effort to review them, so I'm building a tool that lets you analyze LLM outputs directly to help developers of LLM apps and agents…
Jan 2026 · trails-red.vercel.app · its alternatives →
- 16

The LLM Evaluation Framework. Contribute to confident-ai/deepeval development by creating an account on GitHub.
2023 · github.com · its alternatives →
- 17

A test runner for agentskills.io-style AI agent skills - darkrishabh/agent-skills-eval
May 2026 · github.com · its alternatives →
- 18

Annotate translation errors, score quality, get PDF reports
2025 · alconost.mt · its alternatives →
- 19
 Spec27▲34
Hi HN! We’re a team of ML validation specialists and we’ve been building /Spec27, a tool for testing whether AI agents still do their job safely and reliably as models, prompts, tools, and surrounding systems change. We started working on this because a lot of current LLM evaluation work seems aimed at scoring general model behavior, while many teams are deploying systems that have a specific mission to fulfill. Many of the tools also assume you have full access to the agent stack and traces so you can place SDKs and Gateways, but a lot of agents are being created on vendor platforms…
Apr 2026 · spec27.ai · its alternatives →
- 20

Find the Best LLM for Your Needs through E2E Testing - Yuyz0112/relia
2024 · github.com · its alternatives →
- 21

Hi HN! Run it: OPENROUTER_API_KEY="sk" npx bff-eval --demo We built a tool to help people take LLM outputs and easily grade them / eval them to know how good an assistant response is. We've built a number of LLM apps, and while we could ship decent tech demos, we were disappointed with how they'd perform over time. We worked with a few companies who had the same problem, and found out scientifically building prompts and evals is far from a solved problem... writing these things feels more like directing a play than coding. Inspired by Anthropic's constitutional ai concepts, and amazing…
2025 · github.com · its alternatives →
- 22
 Argmin AI▲32
Hey, HN community! We've built Argmin AI after shipping LLM features where the demo worked, then the bill and latency got unpredictable in production. Prompts expanded, context grew, retrieval got noisy, retries appeared, and agent workflows added loops. Argmin AI optimizes LLM-related expenses as a system: 1. prompt and context efficiency 2. model selection and routing 3. RAG inefficiencies and caching opportunities 4. agent workflows (tool calls, retries, loop control) Changes are validated with evals and guardrails (tests, gates, judges), tailored to your quality definition and goals.…
Jul 2026 · argminai.com · its alternatives →
- 23

Deepmark AI enables a unique testing environment for language models (LLM) assessment on task-specific metrics and on your own data so your GenAI-powered solution has predictable and reliable performance. - IngestAI/deepmark
2023 · github.com · its alternatives →
- 24

Also compare
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →