AI · alternatives · 2026

24 alternatives to RagMetrics
We built live AI evaluation to detect hallucinations, grounding issues, and drift as outputs are generated. This helps teams move GenAI from pilots into production.
Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes.
- 1
 Athina AI▲509
Monitor LLMs and automatically detect hallucinations in prod
2024 · athina.ai · its alternatives →
- 2
 LLM Stats▲293
I was overspending on GPT-4o. It was really hard to compare different models I could switch to, so I built this LLM comparison tool. It shows leaderboards, pricing, and performance data across 100+ LLMs (including all major providers and open-source models). Key features: - Live pricing comparisons - Benchmark Scores (MMLU, HumanEval, GPQA, etc.) - Context length vs cost analysis - Speed/throughput tests across providers - Quality vs price visualizations - Open source (all data verifiable) Try it out: https://llmstats.com I'd like to know your opinion :) Tech stack: Next.js,…
Oct 2025 · llm-stats.com · its alternatives →
- 3

Hi all! This morning, we released a new Apache 2.0 licensed model on HuggingFace for detecting hallucinations in retrieval augmented generation (RAG) systems. What we've found is that even when given a "simple" instruction like "summarize the following news article," every LLM that's available hallucinates to some extent, making up details that never existed in the source article -- and some of them quite a bit. As a RAG provider and proponents of ethical AI, we want to see LLMs get better at this. We've published an open source model, a blog more thoroughly describing our methodology (and…
2023 · vectara.com · its alternatives →
- 4
 traceAI▲273
Open-source LLM tracing that speaks GenAI, not HTTP.
Apr 2026 · github.com · its alternatives →
- 5

- 6
 Argmin AI▲32
Hey, HN community! We've built Argmin AI after shipping LLM features where the demo worked, then the bill and latency got unpredictable in production. Prompts expanded, context grew, retrieval got noisy, retries appeared, and agent workflows added loops. Argmin AI optimizes LLM-related expenses as a system: 1. prompt and context efficiency 2. model selection and routing 3. RAG inefficiencies and caching opportunities 4. agent workflows (tool calls, retries, loop control) Changes are validated with evals and guardrails (tests, gates, judges), tailored to your quality definition and goals.…
Jul 2026 · argminai.com · its alternatives →
- 7

I have been working in AI space for a while now, first at FAANG with ML since 2021, then with LLM in start-ups since early 2023. I think LLM Application development is extremely iterative, more so than any other types of development. This is because to improve an LLM application performance (accuracy, hallucinations, latency, cost), you need to try various combinations of LLM models, prompt templates (e.g., few-shot, chain-of-thought), prompt context with different RAG architecture, different agent architecture, and more. There are thousands of possible combinations and you need a process…
2024 · github.com · its alternatives →
- 8AF
We’ve built an AI risk assessment tool designed specifically for GenAI/LLM applications. It's still early, but we’d love your feedback. Here’s what it does: 1. it performs comprehensive AI risk assessments by analyzing your codebase against different AI regulation/framework or even internal policies. It identifies potential issues and suggests fixes directly through one click PRs. 2. the first framework the platform supports is OWASP Top 10 for LLM Applications 2025, upcoming framework will be ISO 42001 as well as custom policy documents. 3. we're a small, early stage team, so the…
2025 · gettavo.com · its alternatives →
- 9
 Deepmark AI▲97
LLM benchmarking tool for task-specific metrics on your data
2023 · github.com · its alternatives →
- 10

- 11

Ragas is an open-source library for evaluating and testing RAG and other LLM applications. Github: https://docs.ragas.io/en/stable/, docs: https://docs.ragas.io/. Ragas provides you with different sets of metrics and methods like synthetic test data generation to help you evaluate your RAG applications. Ragas started off by scratching our own itch for evaluating our RAG chatbots last year. Problems Ragas can solve - How do you choose the best components for your RAG, such as the retriever, reranker, and LLM? - How do you formulate a test dataset…
2024 · github.com · its alternatives →
- 12
 Trails▲81
Hey all, Justin here. I previously built Phind, the AI search engine for developers. One of the biggest problems we had there was figuring out what went wrong with bad searches. We had tons of searches per day, but less than 1% of users gave any explicit feedback. So we were either manually digging through searches or making general system improvements and hoping they helped. This problem gets harder with agents. Traces are longer and more complex. It takes more effort to review them, so I'm building a tool that lets you analyze LLM outputs directly to help developers of LLM apps and agents…
Jan 2026 · trails-red.vercel.app · its alternatives →
- 13Langtrace AI▲119
Improve your LLM apps with open-source observability tool
2024 · langtrace.ai · its alternatives →
- 14

Deepmark AI enables a unique testing environment for language models (LLM) assessment on task-specific metrics and on your own data so your GenAI-powered solution has predictable and reliable performance. - IngestAI/deepmark
2023 · github.com · its alternatives →
- 15

Annotate translation errors, score quality, get PDF reports
2025 · alconost.mt · its alternatives →
- 16

🐢 Open-Source Evaluation & Testing library for LLM Agents - Giskard-AI/giskard-oss
2024 · github.com · its alternatives →
- 17AT
I recently built a small open-source tool to benchmark different LLM API endpoints — including OpenAI, Claude, and self-hosted models (like llama.cpp). It runs a configurable number of test requests and reports two key metrics: • First-token latency (ms): How long it takes for the first token to appear • Output speed (tokens/sec): Overall output fluency Demo: https://llmapitest.com/ Code: https://github.com/qjr87/llm-api-test The goal is to provide a simple, visual, and reproducible way to evaluate performance across different LLM providers, including…
2025 · llmapitest.com · its alternatives →
- 18
Uncover AI bias with GENbAIs: Your LLM fairness checker!
2025 · genbais.com · its alternatives →
- 19
 Spec27▲34
Hi HN! We’re a team of ML validation specialists and we’ve been building /Spec27, a tool for testing whether AI agents still do their job safely and reliably as models, prompts, tools, and surrounding systems change. We started working on this because a lot of current LLM evaluation work seems aimed at scoring general model behavior, while many teams are deploying systems that have a specific mission to fulfill. Many of the tools also assume you have full access to the agent stack and traces so you can place SDKs and Gateways, but a lot of agents are being created on vendor platforms…
Apr 2026 · spec27.ai · its alternatives →
- 20

Hey HN, Joe and Ethan from Tonic.ai here. We just released a new open-source python package for evaluating the performance of Retrieval Augmented Generation (RAG) systems. Earlier this year, we started developing a RAG-powered app to enable companies to talk to their free-text data safely. During our experimentation, however, we realized that using such a new method meant that there weren’t industry-standards for evaluation metrics to measure the accuracy of RAG performance. We built Tonic Validate Metrics (tvalmetrics, for short) to easily calculate the benchmarks we needed to meet in…
2023 · github.com · its alternatives →
- 21
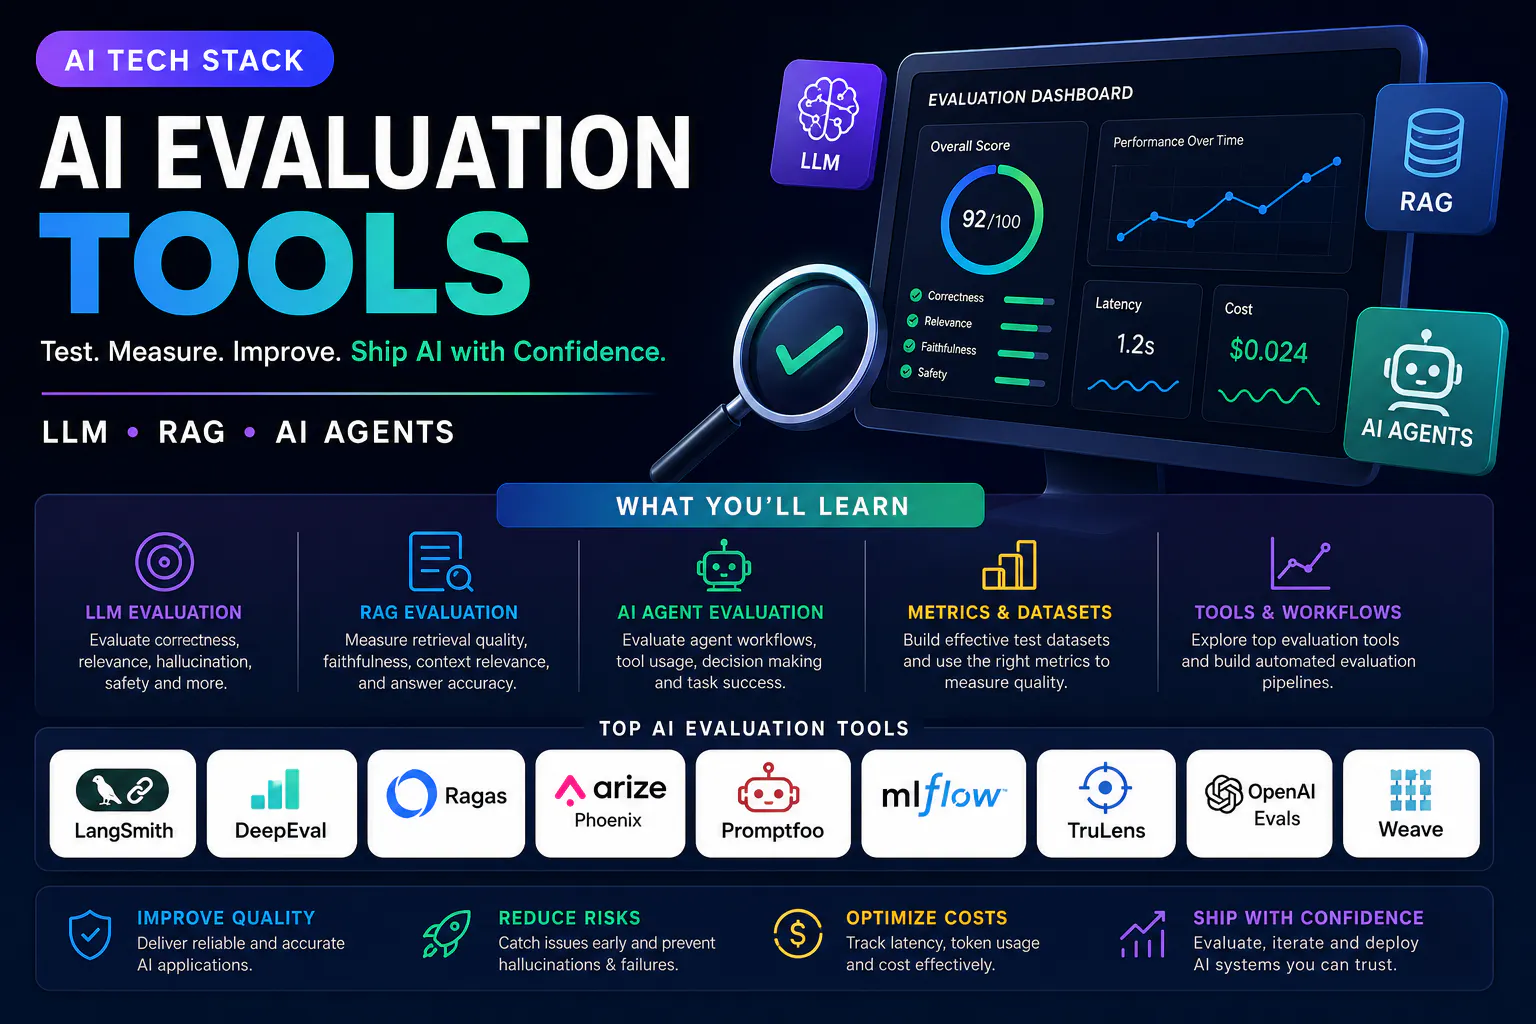
Test LLMs, RAG & AI Agents with Confidence
Aug 2026 · khayyamshah2007.blogspot.com · its alternatives →
- 22

An open source Next app template to monitor your AI apps
2025 · github.com · its alternatives →
- 23

The first GPT-based solution that uses hallucinations from LLMs for divergent thinking to generate new and novel ideas. Hallucinations are often seen as a negative thing, but what if they could be used for our advantage? dreamGPT is here to show you how. The goal of dreamGPT is to explore as many possibilities as possible, as opposed to most other GPT-based solutions which are focused on solving specific problems.
2023 · github.com · its alternatives →
- 24
Spot where your LLM might make mistakes on documents
2025 · hallucina-gen.actualization.ai · its alternatives →

Also compare
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →