Dev tools · alternatives · 2026

24 alternatives to Audino – Open-Source Audio and Speech Annotation Tool
Open source audio annotation tool for humans. Contribute to midas-research/audino development by creating an account on GitHub.
Audino is an open-source tool for annotating audio and speech data. Built for developers and researchers who need to label audio content, it provides a straightforward interface for marking and organizing audio… Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes. Prices are shown for the 1 we have checked on their own sites, 1 of them free or with a free tier. Audino – Open-Source Audio and Speech Annotation Tool launched in 2020; newer entries below may have overtaken it.
- 1
- 2

- 3
 Audioscribe▲288
Free and open-source AI to turn voice into structured notes
2024 · audioscribe.wordware.ai · its alternatives →
- 4AE
2022 · anno.so · its alternatives →
- 5
- 6
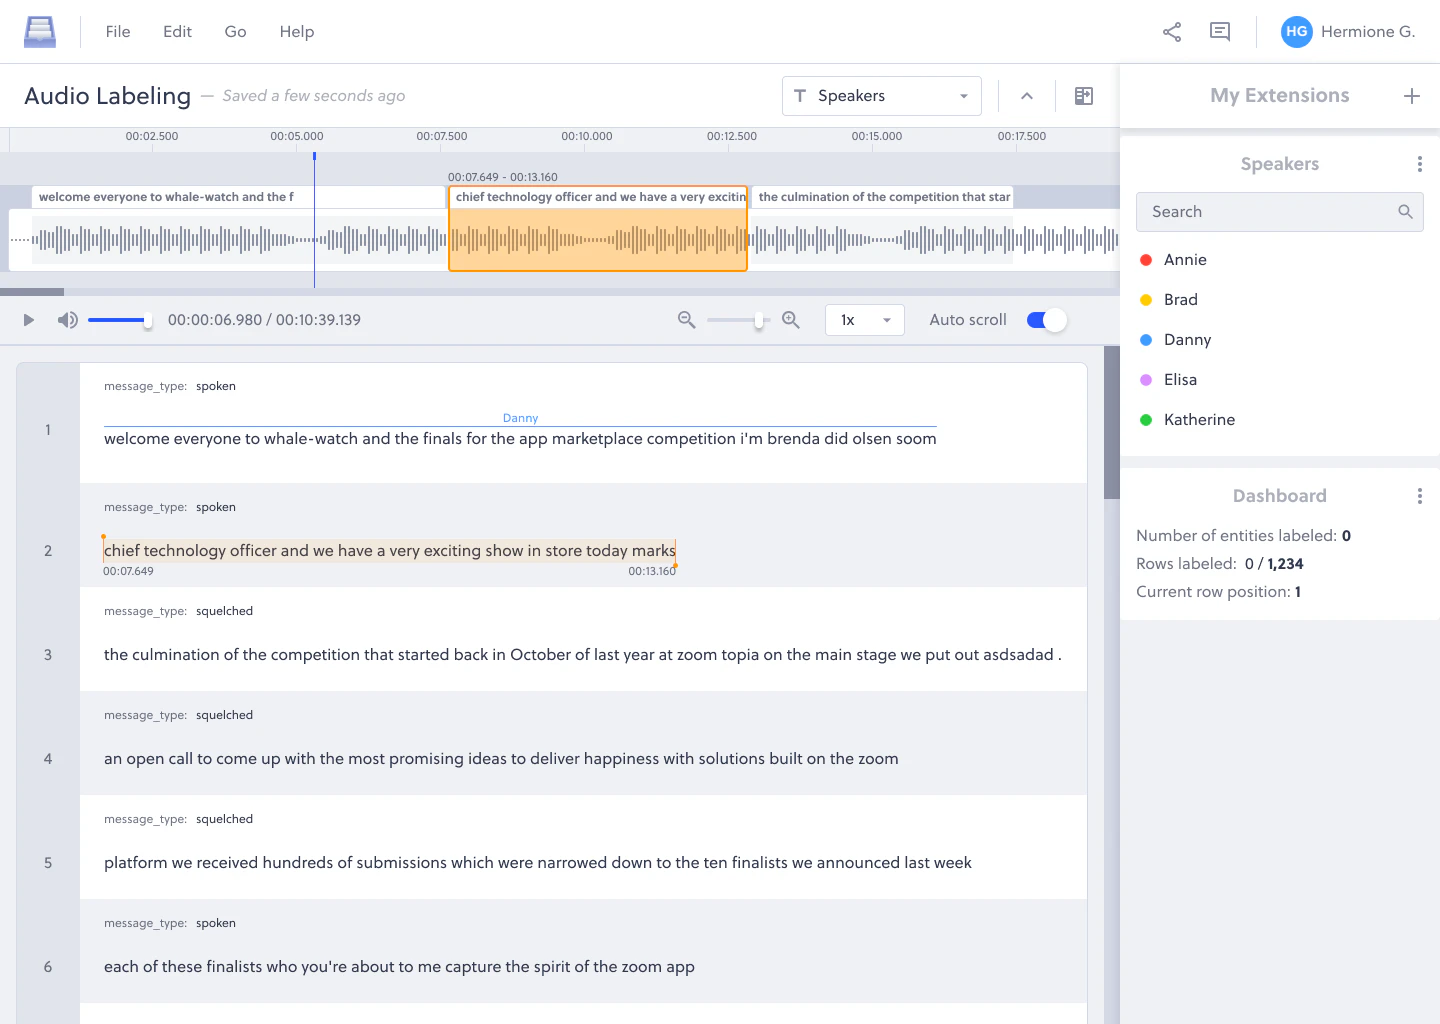
Audio file transcription, time stamping and annotation
2021 · datasaur.ai · its alternatives →
- 7

Voxos is an open-source desktop voice assistant that aims to put Clippy to shame while supporting new desktop workflows powered by LLMs. Tired of copy and pasting ChatGPT responses between your web browser and IDE? Does your copilot not quite do what you need it to do? I invite you to give Voxos a try and maybe even become a contributor!
2024 · gitlab.com · its alternatives →
- 8

- 9

- 10

State-of-the-art (ranked #1 Aug 2022) German Speech Recognition in 284 lines of C++. This is a 100% private 100% offline 100% free CLI tool. - DeutscheKI/tevr-asr-tool
2022 · github.com · its alternatives →
- 11
First TTS model to support all 22 Indic languages + English
2024 · its alternatives →
- 12

Here is a tool I built initially for myself to help with my German and Greek language studies. It started as a hack for creating Anki cards from native language audio. It extracts the words, finds their base forms (lemmas) and groups the examples by the lemma. At some point I realised that I have a transcription with word level timestamps that opens a lot of other opportunities. So I added a mode to click the first and last word in the transcript and it starts looping with the right gap and repeat count. Another feature I use a lot is selecting an audio fragment, sending a predefined prompt…
Jun 2026 · lingochunk.com · its alternatives →
- 13

AOO is a lightweight and flexible peer-to-peer audio streaming and messaging solution. It allows to send audio and messages in real-time and on demand between network endpoints - not only in local networks, but also over the public internet! The C/C++ library can be easily embedded in host applications or plugins. It even runs on embedded devices, such as the ESP32. In addition, the project contains a Pure Data external and a SuperCollider extension. The following article provides a high level introduction and demonstrates some use cases:…
2024 · aoo.iem.sh · its alternatives →
- 14
- 15EA
Transcribe audio from your device microphone using 100% local / client-side processing.
2023 · ermine.ai · its alternatives →
- 16MA
I am excited to announce a new tool for music producers and audio enthusiasts - a music audio search engine. With just a simple description of the groove you're looking for, our semantic search engine will output the most similar audio in seconds. I used the Freesound.org API to upload over 3,000 grooves to MongoDB, and combined all the relevant data such as tags, title, description, BPM, etc. into OpenAI's Text-Davinci to generate a unique description of each sound. I then embedded these descriptions using the Ada Embeddings Model and inserted them into Pinecone DB vector database, making…
2023 · muzic-sage.vercel.app · its alternatives →
- 17

Production ASR for noisy multilingual audio
Apr 2026 · microsoft.ai · its alternatives →
- 18

Working online speech recognition based on RNN Transducer. ( Trained model release available in release ) - theblackcat102/edgedict
2020 · github.com · its alternatives →
- 19

- 20
 I generated 70k audiobooks with OpenAI Text-to-Speechfree tier, from $15/mo▲140
Hey HN. I’m Ivan, hacker from Ukraine. For about a year, I was working on Listenly — an app to listen to text content with OpenAI's natural-sounding text-to-speech model. At some moment, I realized that it would be cool to take all the public domain e-books and create audio versions for them. So I did it... kind-of. It would cost an immense amount of money to generate all the audio right away (OpenAI TTS costs approximately $0.84/hour of audio; 11labs, for comparison, is 10 times more expensive). So, I took a more gradual approach. I took all the metadata from the Project Gutenberg…
2024 · listenly.io · its alternatives →
- 21
- 22

End-to-end Automatic Speech Recognition for Madarian and English in Tensorflow - GitHub - zzw922cn/Automatic_Speech_Recognition: End-to-end Automatic Speech Recognition for Madarian and English in Tensorflow
2017 · github.com · its alternatives →
- 23

Hi HN! Last year the project I launched here got a lot of good feedback on creating speech to speech AI on the ESP32. Recently I revamped the whole stack, iterated on that feedback and made our project fully open-source—all of the client, hardware, firmware code. This Github repo turns an ESP32-S3 into a realtime AI speech companion using the OpenAI Realtime API, Arduino WebSockets, Deno Edge Functions, and a full-stack web interface. You can talk to your own custom AI character, and it responds instantly. I couldn't find a resource that helped set up a reliable, secure websocket (WSS) AI…
2025 · github.com · its alternatives →
- 24

Annotate and share your music with ease
2023 · krock.io · its alternatives →
Also compare
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →