Dev tools · alternatives · 2026
24 alternatives to SirixDB – Storing and Querying of Temporal Data (Java and Open Source)
I'm developing a storage system for versioning data at the subfile level, especially well suited for SSDs due to its log-structured COW nature. It implements a novel versioning algorithm called sliding snapshot, a diff-algorithm which makes use of our stable record-identifiers and optionally hashes, another diff algorithm for importing similar XML-documents as a versioned resource as well as novel XPath axis to navigate not only in space, but also in time. Recently, I've implemented a higher level, asynchronous REST-API with Kotlin (Coroutines) and Vert.x in a seperate module. The system is…
SirixDB is an open-source Java storage system designed for versioning data at the subfile level, optimized for solid-state drives. It features a sliding snapshot algorithm for efficient version management and allows… Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes. Prices are shown for the 1 we have checked on their own sites, 1 of them free or with a free tier. SirixDB – Storing and Querying of Temporal Data (Java and Open Source) launched in 2018; newer entries below may have overtaken it.
- 1SV
I've already posted yesterday, but I'd really love to get comments, any kind of questions, suggestions and help would be greatly appreciated as it's an Open Source project of mine (and was for others during my studies at the University of Konstanz 6 years ago). Since then I spent countless ours to bring forth the idea of a versioned storage system, especially well suited for analytical tasks for timd-varying data. Especially I'd love to discuss what documentation you need, which next steps are necessary (JSON, Cloud...), API additions or changes... I've updated the README quiet a bit, such…
2018 · its alternatives →
- 2

I had already posted the project a couple of years ago, and it gained some interest, but a lot of stuff has been done since then, especially regarding performance, a completely new JSON store, a REST API, various internals refactored, an improved JSONiq based query engine allowing updates, implementing set-oriented join optimizations, a now already dated web UI, a new Kotlin based CLI, a Python and TypeScript client to ease the use of Sirix... First prototypes from a precursor stem already from 2005. So, what is it all about? The system uses ideas from ZFS (a keyed index trie, storing…
2023 · github.com · its alternatives →
- 3
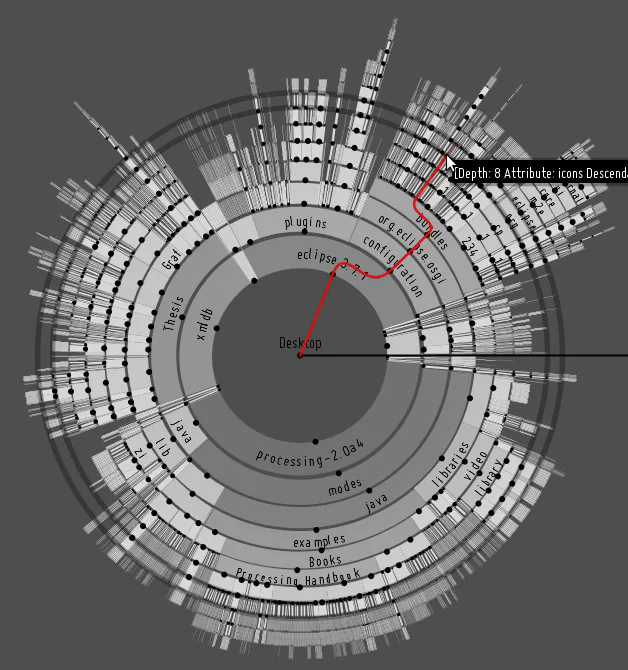
Sirix stores snapshots with a novel versioning approach
2018 · sirix.io · its alternatives →
- 4

:man: a simple, git diffable JSON database on yer filesystem. By the power of NodeJS - DO-SAY-GO/sirdb
2020 · github.com · its alternatives →
- 5

Recently created a minimal persistent relational database in Go. Main focus was on implementing & understanding working the of database, storage management & transaction handling. Use of B+ Tree for storage engine(support for indexing), managing a Free List (for reusing nodes), Support for transactions, Concurrent Reads. Still have many things to add & fix like query processing being one of the main & fixing some bugs Repo link - https://github.com/Sahilb315/AtomixDB Would love to hear your thoughts
2025 · github.com · its alternatives →
- 6DA
Hey HN! I’ve written a bunch of WebSocket servers over the years to do simple things like state synchronization, WebRTC signaling, and notifying a client when a backend job was run. I realized that if I had a simple way to create a private, temporary, mini-redis that the client could talk to directly, it would save a lot of time. So we created DriftDB. In addition to the open source server that you can run yourself, we also provide https://jamsocket.live where you can use an instance we host on Cloudflare’s edge (~13ms round trip latency from my home in NY). You may have seen my…
2023 · driftdb.com · its alternatives →
- 7

Hey HN! I built a proof-of-concept for AI memory using Git instead of vector databases. The insight: Git already solved versioned document management. Why are we building complex vector stores when we could just use markdown files with Git's built-in diff/blame/history? How it works: Memories stored as markdown files in a Git repo Each conversation = one commit git diff shows how understanding evolves over time BM25 for search (no embeddings needed) LLMs generate search queries from conversation context Example: Ask "how has my project evolved?" and it uses git diff to show actual…
2025 · github.com · its alternatives →
- 8

🦉⚡️Serverless, distributed vector database as an API - TimeSurgeLabs/athenadb
2024 · github.com · its alternatives →
- 9AT
A bunch of developers and myself have created RepliByte - an open-source tool to seed a development database from a production database. Features: - Support data backup and restore for PostgreSQL, MySQL and MongoDB - Replace sensitive data with fake data - Works on large database (> 10GB) (read Design) - Database Subsetting: Scale down a production database to a more reasonable size - Start a local database with the prod data in a single command - On-the-fly data (de)compression (Zlib) - On-the-fly data de/encryption (AES-256) - Fully stateless (no server, no daemon) and lightweight…
2022 · its alternatives →
- 10

Hey HN, we want to share HelixDB (https://github.com/HelixDB/helix-db/), a project a college friend and I are working on. It’s a new database that natively intertwines graph and vector types, without sacrificing performance. It’s written in Rust and our initial focus is on supporting RAG. Here’s a video runthrough: https://screen.studio/share/szgQu3yq. Why a hybrid? Vector databases are useful for similarity queries, while graph databases are useful for relationship queries. Each stores data in a way that’s best for its main type of query (e.g.…
2025 · github.com · its alternatives →
- 11

Hey HN! We’ve built Pretzel, an open-source data exploration and visualization tool that runs fully in the browser and can handle large files (200 MB CSV on my 8gb MacBook air is snappy). It’s also reactive - so if, for example, you change a filter, all the data transform blocks after it re-evaluate automatically. You can try it here: https://pretzelai.github.io/ (static hosted webpage) or see a demo video here: https://www.youtube.com/watch?v=73wNEun_L7w You can play with the demo CSV that’s pre-loaded (GitHub data of text-editor adjacent projects) or upload…
2024 · github.com · its alternatives →
- 12DD
Gleb, Alex, Erez and Simon here – we are building an open-source tool for comparing data within and across databases at any scale. The repo is at https://github.com/datafold/data-diff, and our home page is https://datafold.com/. As a company, Datafold builds tools for data engineers to automate the most tedious and error-prone tasks falling through the cracks of the modern data stack, such as data testing and lineage. We launched two years ago with a tool for regression-testing changes to ETL code…
2022 · its alternatives →
- 13PD
PicoMQ is a Rust server for Durable Streams, built on Object Store. Cheap, URL-addressable, granular streams (create/append/read/long-poll/SSE), with Pico Protocol or Durable Streams Protocol as the facade. S3Stream is the stream storage primitive, used in AutoMQ, shipped as a Rust library. Coordination is a command log in Postgres.
Aug 2026 · picomq.com · its alternatives →
- 14

A Go SQL query builder and struct mapper. Contribute to samonzeweb/godb development by creating an account on GitHub.
2016 · github.com · its alternatives →
- 15
 TABLUM.IO▲159
Turn CSV, XML & JSON into a live analysis-ready SQL database
2023 · tablum.io · its alternatives →
- 16

Long-simmering side project that is finally ready to see the light. HAMTs are a cool persistent data structure and implementing one has been a lot of fun. Beyond the code, there is likely some value in the extensive and largely complete implementation docs; basic benchmarks are linked in the README, too. Kind of aiming to be "the libavl for HAMTs". That is obviously a high and aspirational bar but a distinct possibility if it stirs up a little interest and/or contribution. Anyways, it's time for this to go out, collect feedback and maybe even some use outside of toy projects. Let me…
2023 · github.com · its alternatives →
- 17

Contribute to Z-Gort/Reservoirs-Lab development by creating an account on GitHub.
2024 · github.com · its alternatives →
- 18

Hey HN, We've been experimenting with a real-time, version-controlled NoDB for Deno & React called GoatDB. The idea is to remove backend complexity while keeping apps fast, offline-resilient, and easy to self-host. Runs on the client – No backend required, incremental queries keep things efficient. Self-hosted & lightweight – Deploy a single executable, no server stack needed. Offline-first & resilient – Clients work independently & can restore state after server outages. Edge-native & fast – Real-time sync happens locally with minimal overhead. Why We Built It: We needed something that’s…
2025 · github.com · its alternatives →
- 19

Hey HN! We are building Epsilla (https://github.com/epsilla-cloud/vectordb), an open-source, self-hostable vector database for semantic similarity search that specializes in low query latency. When do we need a vector database? For example, GPT-3.5 has a 16k context window limit. If we want to let it answer a question about a 300 page book, we cannot put the whole book content into the context. We have to choose the sections of the book that are most relevant to the question. Vector database is specialized at ranking and picking the most relevant content from a large pool…
2023 · github.com · its alternatives →
- 20

Over the past few months, we've been building Prism; a fast, developer-first observability UI that's deeply integrated with our open-source database, Parseable. Prism is designed for engineers who debug distributed systems, sometimes at odd hours, and need answers right now, without having to deal with five different tools. Backstory: We spoke to dozens of observability practitioners in large enterprises. Across the board, we heard two things: (1)The RoI on observability tools is hard to justify. (2)OSS leads to tool sprawl, metrics in Grafana, logs in ELK, traces… somewhere. We wanted a…
2022 · parseable.com · its alternatives →
- 21AF
2015 · probablyfine.co.uk · its alternatives →
- 22HA
Hi all, we recently open sourced the first version of Hashquery, a Python library which lets you model analytics, DRY up common logic, and execute it against a database or warehouse. We were originally rendering SQL directly for all our queries, but that spiraled out of control with more complex analysis; the SQL needed to be changed sporadically for each new database dialect (BigQuery, Redshift, Aethena, Postgres, etc etc) and the SQL fragments were very challenging to reuse (and so fragments were copy-pasted all over). ~~~ Advantages we think it has over writing SQL by hand: - Queries are…
2024 · hashquery.dev · its alternatives →
- 23

`mandala` is a framework I wrote to automate tracking ML experiments for my research. It differs from other experiment tracking tools by making persistence, query and versioning logic a generic part of the programming language itself, as opposed to an external logging tool you must learn and adapt to. The goal is to be able to write expressive computational code without thinking about persistence (like in an interactive session), and still have the full benefits of a versioned, queriable storage afterwards. Surprisingly, it turns out that this vision can pretty much be achieved with two…
2024 · github.com · its alternatives →
- 24

Hey HN, I’ve built Fahmatrix, a minimal, fast Java library for working with tabular data — inspired by Python’s pandas, but designed for performance and simplicity on the JVM. After working extensively with Python’s data stack, I often ran into limitations related to speed, especially in larger or long-running data workflows. So I built Fahmatrix from scratch to offer similar APIs for manipulating CSVs, performing summary statistics, slicing rows/columns, and more — but all in Java. Features: Lightweight and dependency-free CSV/TSV import with auto-headers Series/DataFrame…
2025 · github.com · its alternatives →
Also compare
- SirixDB – versioning through efficient snapshotting alternatives
- SirixDB – Bitemporal binary JSON database system and event store alternatives
- SirixDB - a temporal storage system alternatives
- Sir – Git-diff-able JSON database on yer filesystem alternatives
- A Database Written in Golang alternatives
- DriftDB – an open source WebSocket backend for real-time apps alternatives
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →