Dev tools · alternatives · 2026
24 alternatives to SirixDB – versioning through efficient snapshotting
I've already posted yesterday, but I'd really love to get comments, any kind of questions, suggestions and help would be greatly appreciated as it's an Open Source project of mine (and was for others during my studies at the University of Konstanz 6 years ago). Since then I spent countless ours to bring forth the idea of a versioned storage system, especially well suited for analytical tasks for timd-varying data. Especially I'd love to discuss what documentation you need, which next steps are necessary (JSON, Cloud...), API additions or changes... I've updated the README quiet a bit, such…
SirixDB is an open-source versioned storage system designed for analytical tasks on time-varying data. It uses efficient snapshotting to track changes across multiple versions. The system includes an asynchronous… Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes. Prices are shown for the 1 we have checked on their own sites, 1 of them free or with a free tier. SirixDB – versioning through efficient snapshotting launched in 2018; newer entries below may have overtaken it.
- 1SS
I'm developing a storage system for versioning data at the subfile level, especially well suited for SSDs due to its log-structured COW nature. It implements a novel versioning algorithm called sliding snapshot, a diff-algorithm which makes use of our stable record-identifiers and optionally hashes, another diff algorithm for importing similar XML-documents as a versioned resource as well as novel XPath axis to navigate not only in space, but also in time. Recently, I've implemented a higher level, asynchronous REST-API with Kotlin (Coroutines) and Vert.x in a seperate module. The system is…
2018 · its alternatives →
- 2

I had already posted the project a couple of years ago, and it gained some interest, but a lot of stuff has been done since then, especially regarding performance, a completely new JSON store, a REST API, various internals refactored, an improved JSONiq based query engine allowing updates, implementing set-oriented join optimizations, a now already dated web UI, a new Kotlin based CLI, a Python and TypeScript client to ease the use of Sirix... First prototypes from a precursor stem already from 2005. So, what is it all about? The system uses ideas from ZFS (a keyed index trie, storing…
2023 · github.com · its alternatives →
- 3
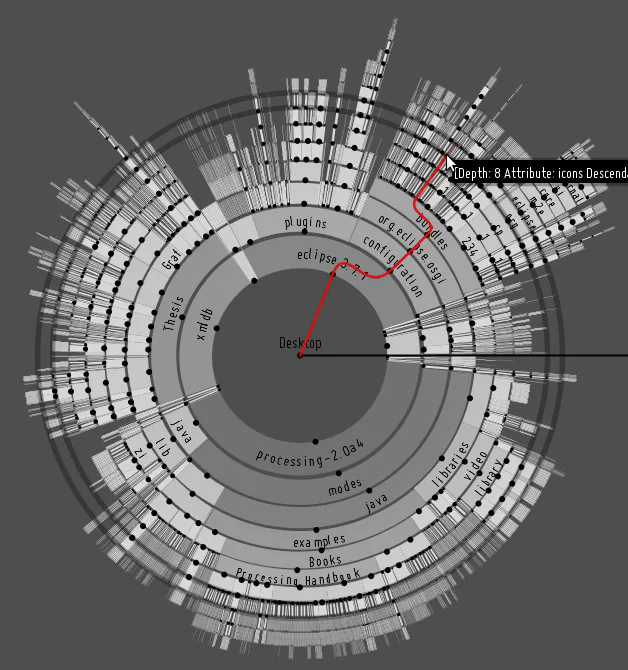
Sirix stores snapshots with a novel versioning approach
2018 · sirix.io · its alternatives →
- 4

:man: a simple, git diffable JSON database on yer filesystem. By the power of NodeJS - DO-SAY-GO/sirdb
2020 · github.com · its alternatives →
- 5

Hey there HN! We’re Joe and Stopa, and today we’re open sourcing InstantDB, a client-side database that makes it easy to build real-time and collaborative apps like Notion and Figma. Building modern apps these days involves a lot of schleps. For a basic CRUD app you need to spin up servers, wire up endpoints, integrate auth, add permissions, and then marshal data from the backend to the frontend and back again. If you want to deliver a buttery smooth user experience, you’ll need to add optimistic updates and rollbacks. We do these steps over and over for every feature we build, which can…
2024 · github.com · its alternatives →
- 6

Hey HN -- thanks for showing interest in this. Happy to collaborate on this project. I'm hoping to get it stable soon so my own family can start using it. I've been working on this for about 10+ years, nights and weekends. It's been really slow going since I only have my own personal data to test it with. I just don't love that my data is primarily stored on someone else's computer up in the cloud. I want my own local copy at least. And while I can download exports from my various accounts, I don't want them to just gather dust and rot on my hard drive. So, Timelinize helps keep that data…
2025 · timelinize.com · its alternatives →
- 7AT
A bunch of developers and myself have created RepliByte - an open-source tool to seed a development database from a production database. Features: - Support data backup and restore for PostgreSQL, MySQL and MongoDB - Replace sensitive data with fake data - Works on large database (> 10GB) (read Design) - Database Subsetting: Scale down a production database to a more reasonable size - Start a local database with the prod data in a single command - On-the-fly data (de)compression (Zlib) - On-the-fly data de/encryption (AES-256) - Fully stateless (no server, no daemon) and lightweight…
2022 · its alternatives →
- 8DA
Hey HN! I’ve written a bunch of WebSocket servers over the years to do simple things like state synchronization, WebRTC signaling, and notifying a client when a backend job was run. I realized that if I had a simple way to create a private, temporary, mini-redis that the client could talk to directly, it would save a lot of time. So we created DriftDB. In addition to the open source server that you can run yourself, we also provide https://jamsocket.live where you can use an instance we host on Cloudflare’s edge (~13ms round trip latency from my home in NY). You may have seen my…
2023 · driftdb.com · its alternatives →
- 9

`mandala` is a framework I wrote to automate tracking ML experiments for my research. It differs from other experiment tracking tools by making persistence, query and versioning logic a generic part of the programming language itself, as opposed to an external logging tool you must learn and adapt to. The goal is to be able to write expressive computational code without thinking about persistence (like in an interactive session), and still have the full benefits of a versioned, queriable storage afterwards. Surprisingly, it turns out that this vision can pretty much be achieved with two…
2024 · github.com · its alternatives →
- 10

Recently created a minimal persistent relational database in Go. Main focus was on implementing & understanding working the of database, storage management & transaction handling. Use of B+ Tree for storage engine(support for indexing), managing a Free List (for reusing nodes), Support for transactions, Concurrent Reads. Still have many things to add & fix like query processing being one of the main & fixing some bugs Repo link - https://github.com/Sahilb315/AtomixDB Would love to hear your thoughts
2025 · github.com · its alternatives →
- 11

Version control for databases: save, restore, and archive snapshots of your database from the command line - infostreams/db
2019 · github.com · its alternatives →
- 12

One year ago I open-sourced my very first 'real' project and shared it here. I was a college student in my senior year and desperately looking for a job. At the time of sharing it i couldn't even afford a domain and naively let someone buy the one i had my eyes on lol. It's been a hell of a year with this blowing up, me moving to another country, and switching 2 jobs. In a year we somehow managed to hit 26k stars, grow a 1000+ person discord community, and support 37 languages. I couldn't be more grateful for the community that helped this grow, but now i don't know what direction to take…
2025 · drawdb.app · its alternatives →
- 13DA
Dear HN, I am Riwaj, the cofounder of dstack.ai (https://github.com/dstackai). A few months ago, we built an online service that allows users to publish data visualizations from Python or R. The idea was to build a tool that did not require additional programming or front-end development for publishing data visualizations. Such a code can be invoked from either Jupyter notebook, RMarkdown, Python, or R scripts. Once the data is pushed, it can be accessed via a browser. Open-sourcing dstack: During our customer discovery phase, we realized that dstack.ai should integrate a lot…
2020 · its alternatives →
- 14HA
Hi all, we recently open sourced the first version of Hashquery, a Python library which lets you model analytics, DRY up common logic, and execute it against a database or warehouse. We were originally rendering SQL directly for all our queries, but that spiraled out of control with more complex analysis; the SQL needed to be changed sporadically for each new database dialect (BigQuery, Redshift, Aethena, Postgres, etc etc) and the SQL fragments were very challenging to reuse (and so fragments were copy-pasted all over). ~~~ Advantages we think it has over writing SQL by hand: - Queries are…
2024 · hashquery.dev · its alternatives →
- 15

Hey HN, We've been experimenting with a real-time, version-controlled NoDB for Deno & React called GoatDB. The idea is to remove backend complexity while keeping apps fast, offline-resilient, and easy to self-host. Runs on the client – No backend required, incremental queries keep things efficient. Self-hosted & lightweight – Deploy a single executable, no server stack needed. Offline-first & resilient – Clients work independently & can restore state after server outages. Edge-native & fast – Real-time sync happens locally with minimal overhead. Why We Built It: We needed something that’s…
2025 · github.com · its alternatives →
- 16

Apache Cloudberry 2.0.0 has been released - the first official release under the Apache Software Foundation. Key highlights: * Built on PostgreSQL 14.x with distributed query processing * Dynamic Tables: automatic, scheduled refresh of query results for real-time analytics * PAX storage format: hybrid row/column storage for better OLAP performance * ASF-compliant updates on dependencies, LICENSE/NOTICE/DISCLAIMER files Apache Cloudberry is derived from PostgreSQL and the last open-source Greenplum Database. It provides massively parallel processing (MPP) capabilities for…
2024 · github.com · its alternatives →
- 17

🦉⚡️Serverless, distributed vector database as an API - TimeSurgeLabs/athenadb
2024 · github.com · its alternatives →
- 18

The most advanced distribution system of NDB Cluster, by Mikael Ronström the inventor of NDB Cluster; made to work for the most advanced ML applications.
2021 · rondb.com · its alternatives →
- 19

Hey HN – Stefan and Elijah here from DAGWorks (http://dagworks.io/, YC W23). If you don’t remember us from our previous HN launch (https://news.ycombinator.com/item?id=35056903), we’re the authors of Hamilton (https://github.com/dagworks-inc/hamilton), an open-source library for building self-documenting, modular dataflows in python that works for data, ML, LLM pipelines, & even web-workflows. We’ve been developing this UI for a while and we’re excited to say we open-sourced it! It comes out of the box with the following capabilities, and…
2024 · github.com · its alternatives →
- 20IB
upscaledb - a blazingly fast embedded key-value store with analytical functions
2016 · upscaledb.com · its alternatives →
- 21

SiriDB is a highly-scalable, robust and super fast time series database. Build from the ground up SiriDB uses a unique mechanism to operate without a global index and allows server resources to be added on the fly. SiriDB's unique query language includes dynamic grouping of time series for easy anal
2017 · github.com · its alternatives →
- 22

Distributed NoSQL Database. Contribute to stephenmcd/curiodb development by creating an account on GitHub.
2015 · github.com · its alternatives →
- 23

The versioned, forkable, syncable database. Contribute to attic-labs/noms development by creating an account on GitHub.
2016 · github.com · its alternatives →
- 24

:man: a simple, git diffable JSON database on yer filesystem. By the power of NodeJS - DO-SAY-GO/sirdb
2020 · github.com · its alternatives →
Also compare
- SirixDB – Storing and Querying of Temporal Data (Java and Open Source) alternatives
- SirixDB – Bitemporal binary JSON database system and event store alternatives
- SirixDB - a temporal storage system alternatives
- Sir – Git-diff-able JSON database on yer filesystem alternatives
- InstantDB – A Modern Firebase alternatives
- Timelinize – Privately organize your own data from everywhere, locally alternatives
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →