Dev tools · alternatives · 2026

24 alternatives to Yomuco – A simple web crawling library for Node.js
Contribute to andraindrops/yomuco development by creating an account on GitHub.
Yomuco is a web crawling library designed for Node.js developers. It provides tools to extract and process data from websites programmatically. The library offers a straightforward approach to web scraping tasks… Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes. Prices are shown for the 1 we have checked on their own sites, 1 of them free or with a free tier. Yomuco – A simple web crawling library for Node.js launched in 2024; newer entries below may have overtaken it.
- 1

Hey HN, This is Jan, founder of Apify, a web scraping and automation platform. Drawing on our team's years of experience, today we're launching Crawlee [1], the web scraping and browser automation library for Node.js that's designed for the fastest development and maximum reliability in production. For details, see the short video [2] or read the announcement blog post [3]. Main features: - Supports headless browsers with Playwright or Puppeteer - Supports raw HTTP crawling with Cheerio or JSDOM - Automated parallelization and scaling of crawlers for best performance - Avoids blocking using…
2022 · crawlee.dev · its alternatives →
- 2
 Context.dev▲814
Hello, My name is Yahia, I've been working on scraping products for a long time and maintain a couple of free sites in my spare time (E.g. knifegeek.io) What prompted this is i've rebuilt scraping infra at every company I've started and finally just made it a product. Pass a URL, get clean markdown, html, images, sitemap or pass a domain, get logos, colors, socials, industry data. Goal is to offer a better service than VC funded competitors at a fraction of the cost. Stealth is included and automatic at no additional cost (normally an upcharge by alternatives). Would love your honest thoughts.
Jul 2026 · context.dev · its alternatives →
- 3

A complete and versatile web scraper. Contribute to ruipgil/scraperjs development by creating an account on GitHub.
2014 · github.com · its alternatives →
- 4

- 5

Crawlee—A web scraping and browser automation library for Node.js to build reliable crawlers. In JavaScript and TypeScript. Extract data for AI, LLMs, RAG, or GPTs. Download HTML, PDF, JPG, PNG, and other files from websites. Works with Puppeteer, Playwright, Cheerio, JSDOM, and raw HTTP. Both headf
2018 · github.com · its alternatives →
- 6DR
I'd like to invite everyone to try out DontBeEvil.rip, an experimental search engine for developers. tl;dr $ alias rip="curl -G -H 'Accept: text/plain' --url https://dontbeevil.rip/search --data-urlencode " $ rip 'q=Heartbleed bug' DontBeEvil.rip is a year long experiment to see if a small team can build a developer-focused search engine that is self-sustaining on $10 monthly subscriptions. It works by only indexing high-quality resources that are relevant to developers. You won't get useless listicles because we'll never crawl them. Relevant urls are harvested from HN,…
2022 · its alternatives →
- 7
 ScrapeNinja▲249
Swiss army knife for high-performance web scraping
2023 · scrapeninja.net · its alternatives →
- 8
 Turn any website into an API (for those who miss Kimono)free tier, from $19/mo▲332
Web scraping made simple — extract data with our free Chrome extension and powerful cloud platform. Turn websites into structured data at scale, via dashboard or API.
2019 · simplescraper.io · its alternatives →
- 9
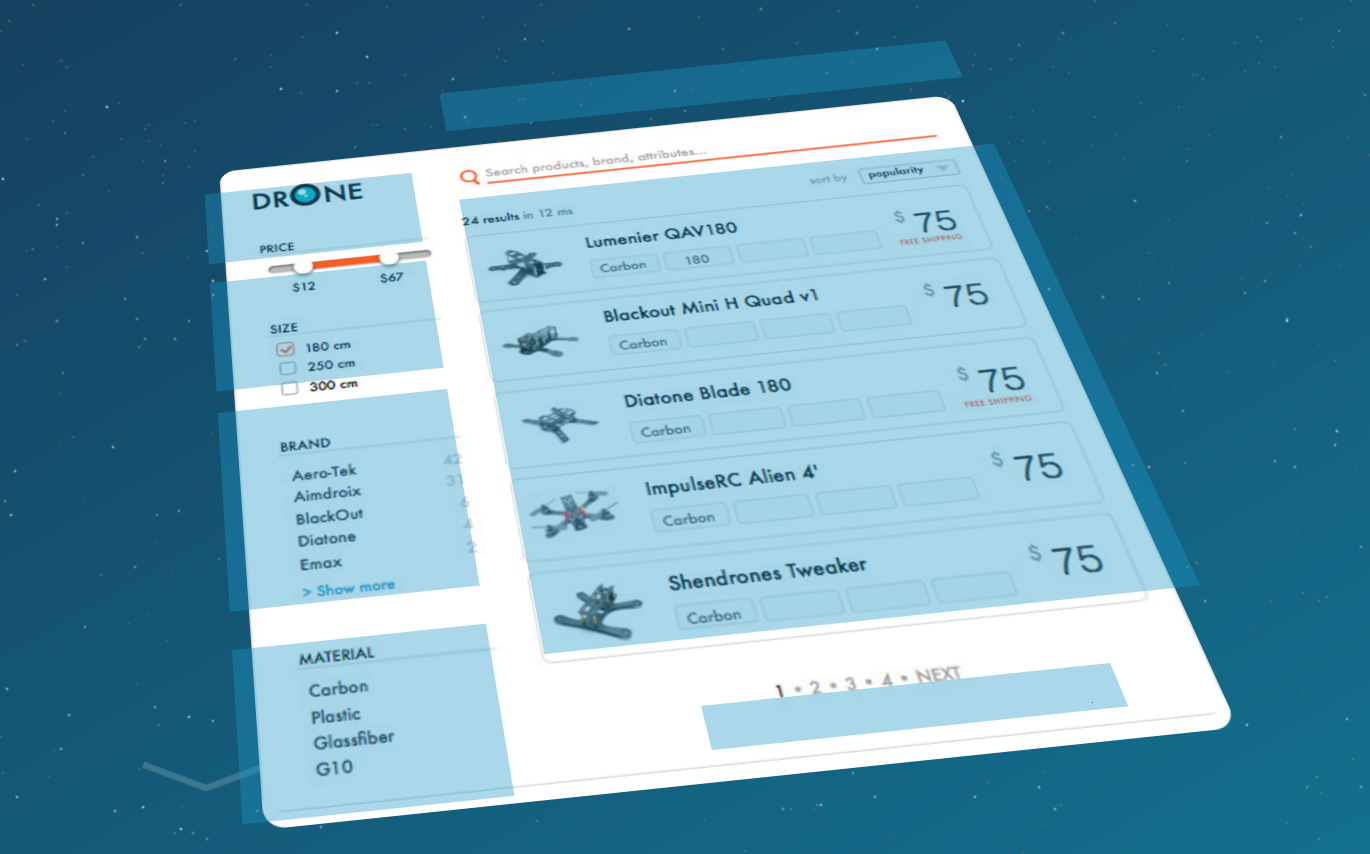
JavaScript UI library for building great search experiences
2015 · community.algolia.com · its alternatives →
- 10

The easiest web scraping API on the web
2019 · scrapingbee.com · its alternatives →
- 11

An agnostic, reactive & minimalist (3kb) JavaScript UI library with direct access to native DOM.
2021 · caldom.org · its alternatives →
- 12

Two months ago, I started building this side-project in the morning, before my full-time job. A visual and easy-to-use web scraping app. Please, roast it a bit so I can work on improving it. Thanks.
2023 · mrscraper.com · its alternatives →
- 13
- 14

We're excited to announce Lowdefy V4, a full-stack web framework built on top of Next.js that simplifies building web applications, internal tools, admin panels, BI dashboards, and CRUD apps using YAML or JSON configuration files. New in V4: Next.js: Lowdefy now runs on top of the Next.js framework. All of Auth.js: App auth is now handled by Auth.js supported providers, adapters and callbacks and events, easy to configure, but all of which can be customized. Plugin extensibility: Apps can now be extended with any npm or pnpm workspace plugins. Our story: We have developed a simple…
2021 · lowdefy.com · its alternatives →
- 15

I built µJS because I wanted AJAX navigation without the verbosity of HTMX or the overhead of Turbo. It intercepts links and form submissions, fetches pages via AJAX, and swaps fragments of the DOM. Single tag, one call to `mu.init()`. No build step, no dependencies. Key features: patch mode (update multiple fragments in one request), SSE support, DOM morphing via idiomorph, View Transitions, prefetch on hover, polling, and full HTTP verb support on any element. At ~5KB gzipped, it's smaller than HTMX (16KB) and Turbo (25KB), and works with any backend: PHP, Python, Go, Ruby, whatever.…
Mar 2026 · mujs.org · its alternatives →
- 16LA
Reactive components with React-like patterns at ~9 KB gzip. Zero dependencies, zero build step, designed for humans and AI agents.
2021 · lemonadejs.net · its alternatives →
- 17JA
a lightweight dependency free javascript micro-library for making collapsable trees with JSON
2017 · maxleiter.github.io · its alternatives →
- 18

Monkberry is blazingly fast, small 1kb and simple JavaScript library for building web user interfaces.
2016 · monkberry.js.org · its alternatives →
- 19

Hi HN! I created this lib in the need of a simple and tiny framework to easily do AJAX-style navigation / replacement of fragments in the page, in a web application. For people who don't want to use client-side-rendering and complex frameworks à la React, there are nowadays a few "HTML-over-the-wire" libraries, like HTMX, Unpoly or this super-tiny one Swap.js :) One other key thing is that no external tool is needed: no bundler, no webpack, no TypeScript compiler, no minification needed. Just write HTML, JS (+ your preferred server-side language: PHP, Python, etc.) and it works. The…
2023 · github.com · its alternatives →
- 20

- 21

Find the origin of any character in the DOM
2019 · fromjs.com · its alternatives →
- 22AP
2018 · scrapy.apki.io · its alternatives →
- 23

We've been building data pipelines that scrape websites and extract structured data for a while now. If you've done this, you know the drill: you write CSS selectors, the site changes its layout, everything breaks at 2am, and you spend your morning rewriting parsers. LLMs seemed like the obvious fix — just throw the HTML at GPT and ask for JSON. Except in practice, it's more painful than that: - Raw HTML is full of nav bars, footers, and tracking junk that eats your token budget. A typical product page is 80% noise. - LLMs return malformed JSON more often than you'd expect, especially with…
Mar 2026 · github.com · its alternatives →
- 24

I needed a lightweight way to archive documentation from a website. wget and similar tools failed to clone the site reliably (missing assets, broken links, etc.), so I ended up building a full website-cloning tool using Node.js + Puppeteer. Repo: https://github.com/jademsee/webclone Feedback, issues, and PRs are very welcome.
Dec 2025 · github.com · its alternatives →
Also compare
- Crawlee – Web scraping and browser automation library for Node.js alternatives
- Context.dev alternatives
- Scraperjs – A versatile web scraper alternatives
- scrape-it alternatives
- Apify SDK – A scalable web crawling and scraping library for JavaScript alternatives
- DontBeEvil.rip: Search, for developers (API, expressions, CLI) alternatives
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →