LoraLand
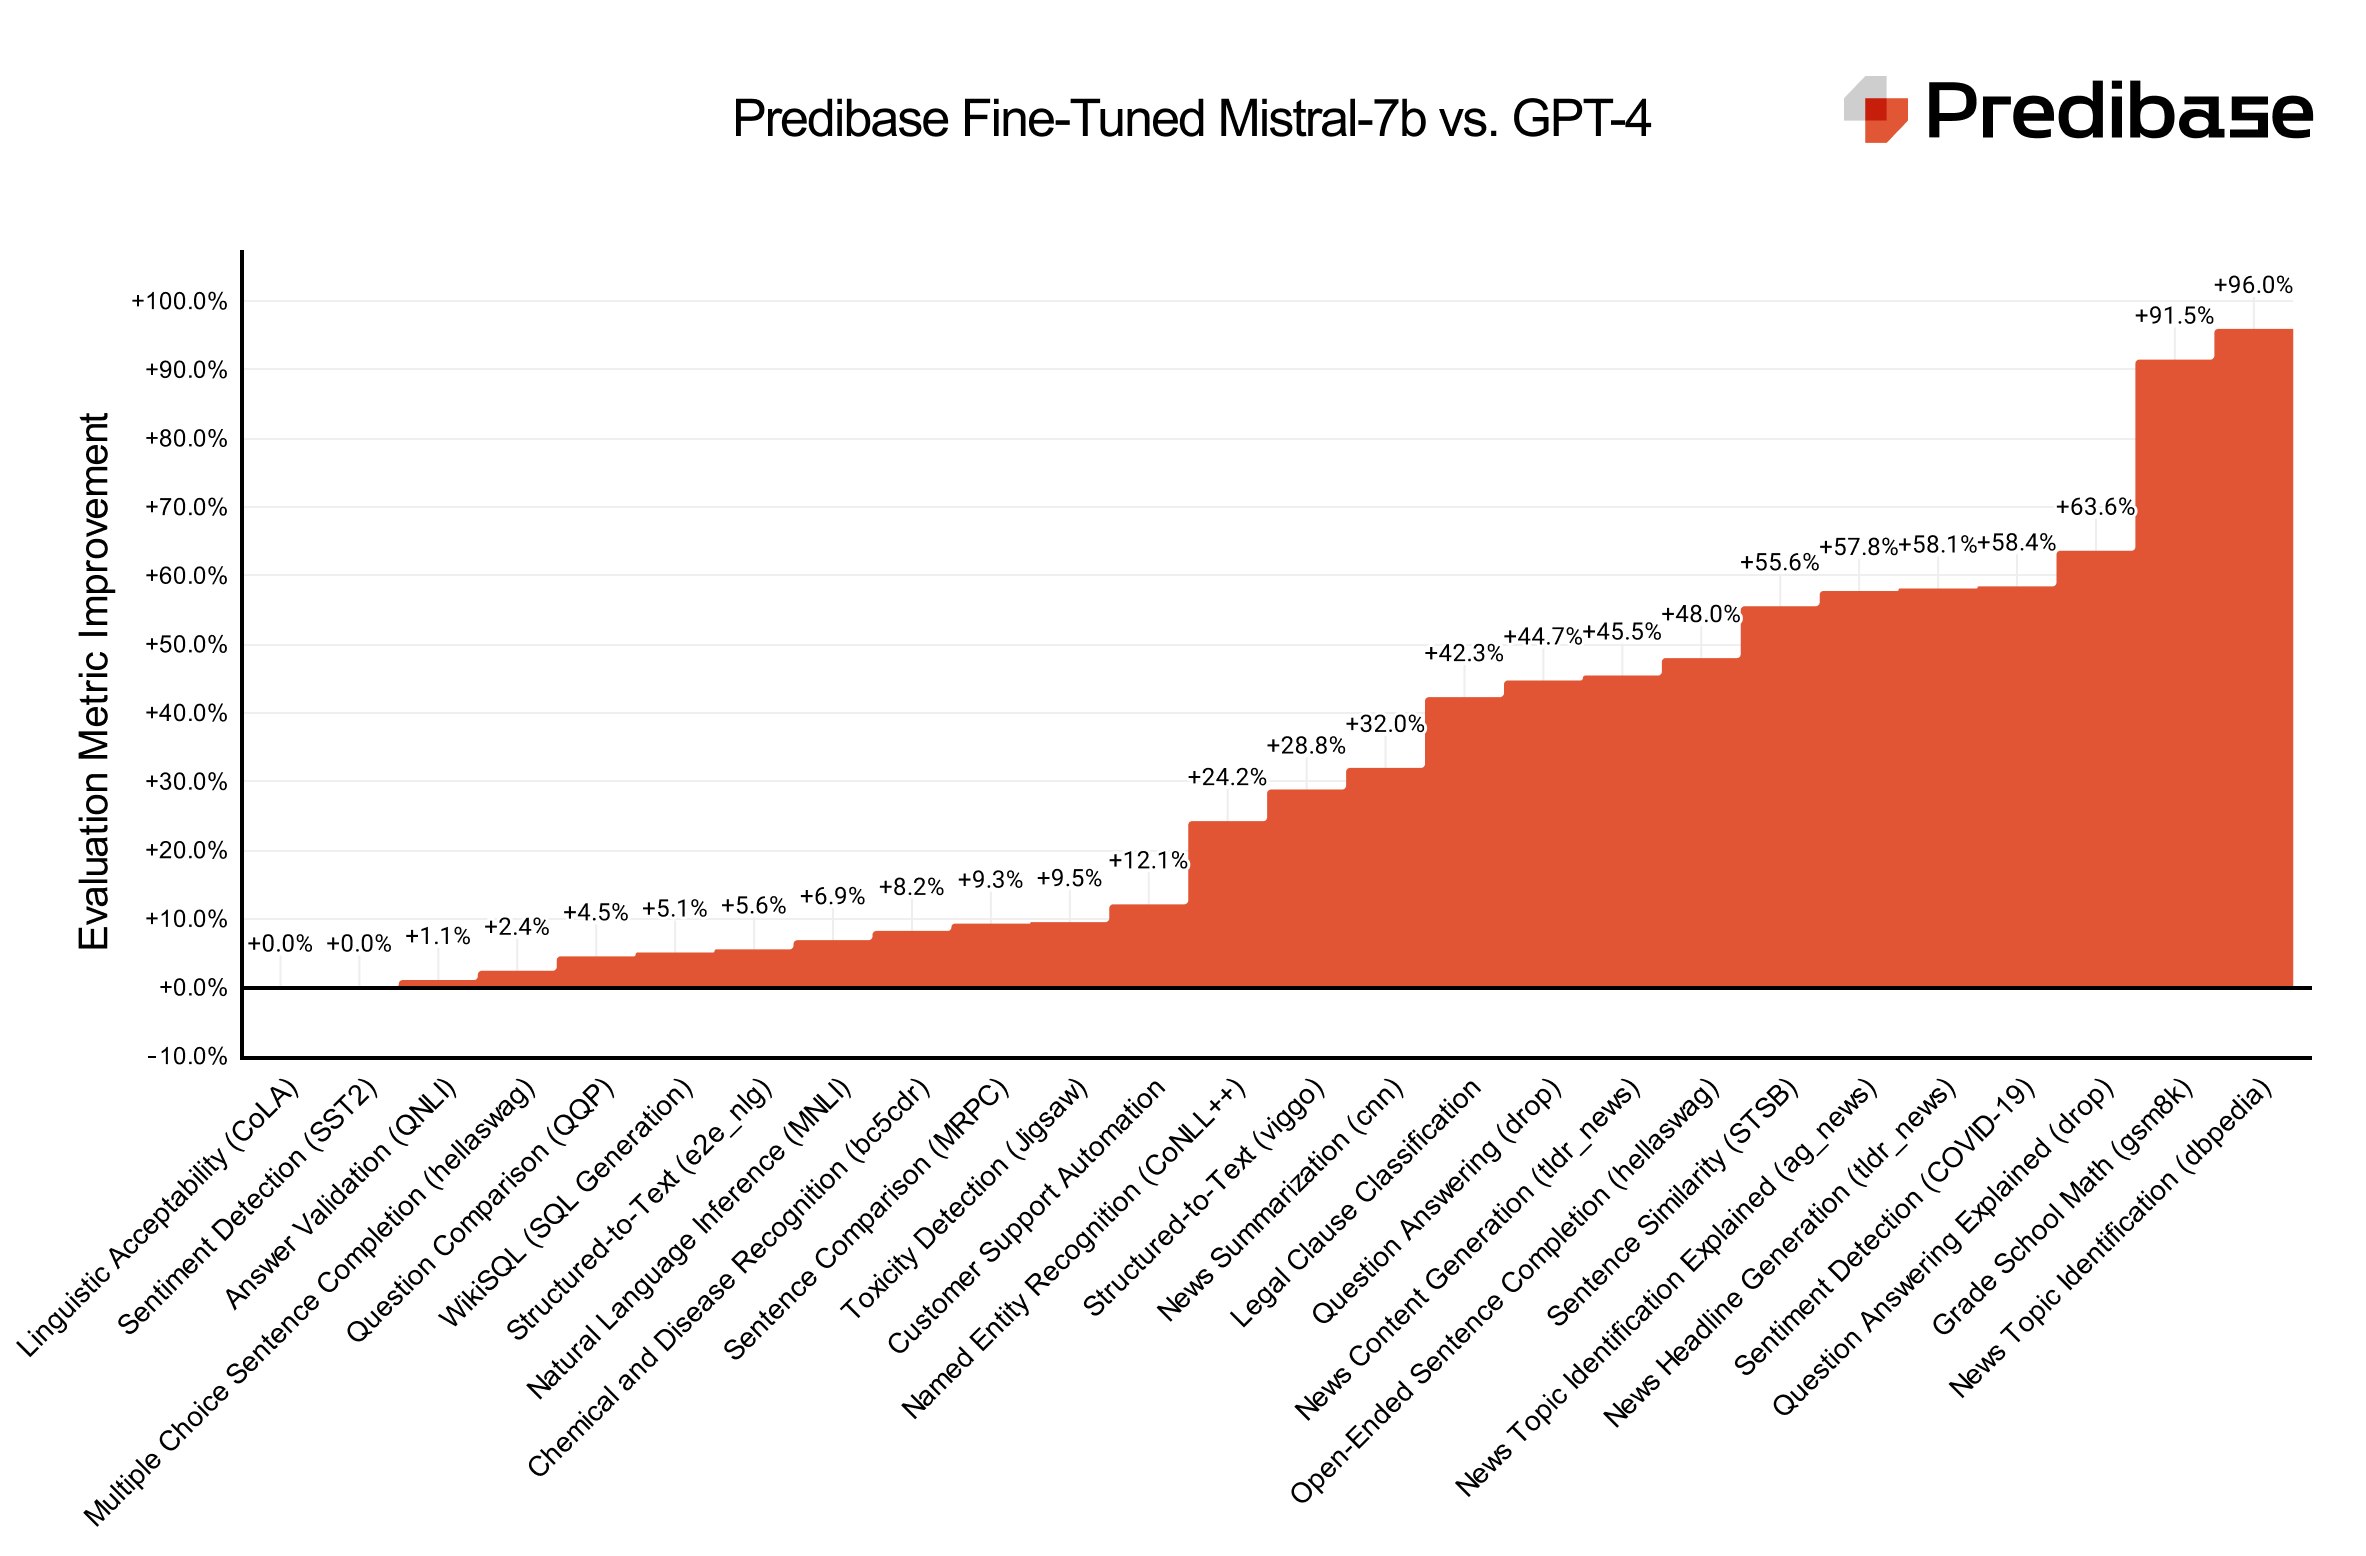
25 fine-tuned Mistral-7b models that outperform GPT-4
LoraLand launched on February 20, 2024 with 11 votes, #1,240 of 3,962 launches that month and more than 50% of that year's launches. The site was not reachable when checked in September 2026.
What it does
All 25 fine-tuned models… 📈 Outperform GPT-4, GPT-3.5-turbo, and mistral-7b-instruct for specific tasks ⚡️ Are cost-effectively served from a single GPU through LoRAX 💰 Were trained for less than $8 each on average
Does a similar job
all alternatives →- L2LoraLand – 25 fine-tuned LLMs that beat GPT-42024 · predibase.com · ▲24
Hi all, today we're excited to launch LoraLand: 25 fine-tuned mistral-7b models that outperform #gpt4 on task-specific applications ranging from sentiment detection to question answering. All 25 fine-tuned models… - Outperform GPT-4, GPT-3.5-turbo, and mistral-7b-instruct for specific tasks - Are cost-effectively served from a single GPU through LoRAX - Were trained for less than $8 each on average You can prompt all of the fine-tuned models today and compare their results to mistral-7b-instruct in real time! We'd love to hear comments and feedback from the community
 Finetune LLaMA-7B on commodity GPUs using your own text2023 · github.com · ▲449
I've been playing around with https://github.com/zphang/minimal-llama/ and https://github.com/tloen/alpaca-lora/blob/main/finetune.py, and wanted to create a simple UI where you can just paste text, tweak the parameters, and finetune the model quickly using a modern GPU. To prepare the data, simply separate your text with two blank lines. There's an inference tab, so you can test how the tuned model behaves. This is my first foray into the world of LLM finetuning, Python, Torch, Transformers, LoRA, PEFT, and Gradio. Enjoy!

 80% faster, 50% less memory, 0% loss of accuracy Llama finetuning2023 · github.com · ▲385
Hi HN! I'm just sharing a project I've been working on during the LLM Efficiency Challenge - you can now finetune Llama with QLoRA 5x faster than Huggingface's original implementation on your own local GPU. Some highlights: 1. Manual autograd engine - hand derived backprop steps. 2. QLoRA / LoRA 80% faster, 50% less memory. 3. All kernels written in OpenAI's Triton language. 4. 0% loss in accuracy - no approximation methods - all exact. 5. No change of hardware necessary. Supports NVIDIA GPUs since 2018+. CUDA 7.5+. 6. Flash Attention support via Xformers. 7. Supports 4bit and 16bit…
 Local fine tuning for Mistral and SDXL, GPU mem/latency optimization2023 · docs.helix.ml · ▲36
100% bootstrapped new startup. It lets you fine tune Mistral-7B and SDXL. In particular, for the LLM fine tuning we implemented a dataprep pipeline that turns websites/pdfs/doc files into question-answer pairs for training the small LLM using an big LLM. It includes a GPU scheduler that can do finegrained GPU memory scheduling (Kubernetes can only do whole-GPU, we do it per-GB of GPU memory to pack both inference and fine tuning jobs into the same fleet) to fit model instances into GPU memory to optimally trade off user facing latency with GPU memory utilization It's a pretty…
More ai this month
the category →


Paintings by AI models: programs run through a simulation of oil paint.
AI · 21d ago · stillwet.art
 PixVerse R2▲381
A real-time world model you can explore and change
AI · 29d ago · world.pixverse.video

Source: Product Hunt launch ↗
Launched alongside, February 2024
the whole month →


 MarketingIdeas.com▲1,230
Never run out of marketing ideas ever again
Growth · 2024 · marketingideas.com