Mashape Analytics - Visualize, Inspect and Monitor API Performance
From APIs to AI, Kong is the fabric of modern connectivity. Centralize LLM access, automate API workflows, and secure your digital ecosystem at scale.
Mashape Analytics - Visualize, Inspect and Monitor API Performance launched on June 24, 2015 with 9 votes, #1,590 of 3,954 launches that month and more than 75% of that year's launches. The site was still online in September 2026, 11 years on.
What it does
Secure, manage, speed up, monetize, and cost-control every LLM, MCP, event, and API request. Tell us a bit about yourself to make the meeting more valuable. The API call dominated the cloud-native era. We helped you become an API-first company. Now the token is king. We'll help you build, run, and govern agents to win this new landscape. Get un-fragmented. Unify your AI cost, security, and risk posture with Kong. Build, deploy, and run agentic infrastructure in a single developer workspace. Eliminate critical security and resilience risks across the entire AI data path. Monetize agent context, and do what it takes to win the new context economy. Build agents. Orchestrate context. Govern…from apianalytics.com
Does a similar job
all alternatives →
- FWFIFA World Cup RESTful API2014 · mashape.com · ▲6
From APIs to AI, Kong is the fabric of modern connectivity. Centralize LLM access, automate API workflows, and secure your digital ecosystem at scale.
 LLM Gateway2025 · llmgateway.io · ▲296
I built an OpenAI-compatible LLM gateway that routes requests to OpenAI, Anthropic, Ollama, vLLM, llama-server, SGLang... anything that speaks /v1/chat/completions. Single Go binary, one YAML config file, no infrastructure. It does the things you'd expect from this kind of gateway... semantic routing via a three-layer cascade (keyword heuristics, embedding similarity, LLM classifier) that picks the best model when clients omit the model field, weighted round-robin load balancing across local inference servers with health checks and failover. The part I think is most…


- ATA tool to benchmark LLM APIs (OpenAI, Claude, local/self-hosted)2025 · llmapitest.com · ▲55
I recently built a small open-source tool to benchmark different LLM API endpoints — including OpenAI, Claude, and self-hosted models (like llama.cpp). It runs a configurable number of test requests and reports two key metrics: • First-token latency (ms): How long it takes for the first token to appear • Output speed (tokens/sec): Overall output fluency Demo: https://llmapitest.com/ Code: https://github.com/qjr87/llm-api-test The goal is to provide a simple, visual, and reproducible way to evaluate performance across different LLM providers, including…
More ai this month
the category →


Paintings by AI models: programs run through a simulation of oil paint.
AI · 22d ago · stillwet.art

 FastRouter.ai▲364
Route requests to the right LLM for cost, latency & quality
AI · 23d ago · fastrouter.ai
Source: Show HN post ↗
Launched alongside, June 2015
the whole month →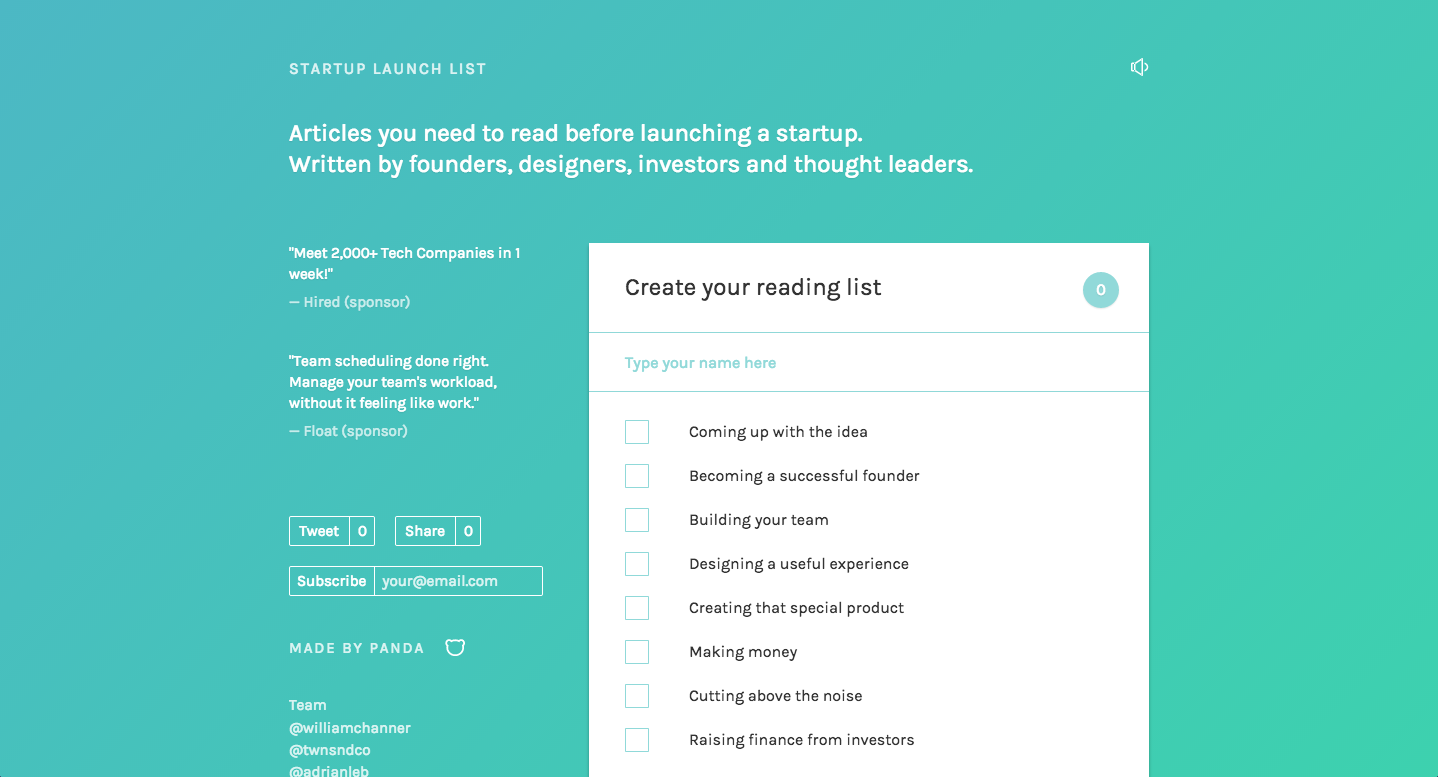 Startup Launch List▲1,251
Articles you need to read before launching a startup.
Growth · 2015 · startuplaunchlist.com

Get any site's company logo with just a URL
Dev tools · 2015 · clearbit.com