
ModelFit
Find the best local LLM your Mac or GPU can actually run
ModelFit launched on July 7, 2026 with 2 votes.
What it does
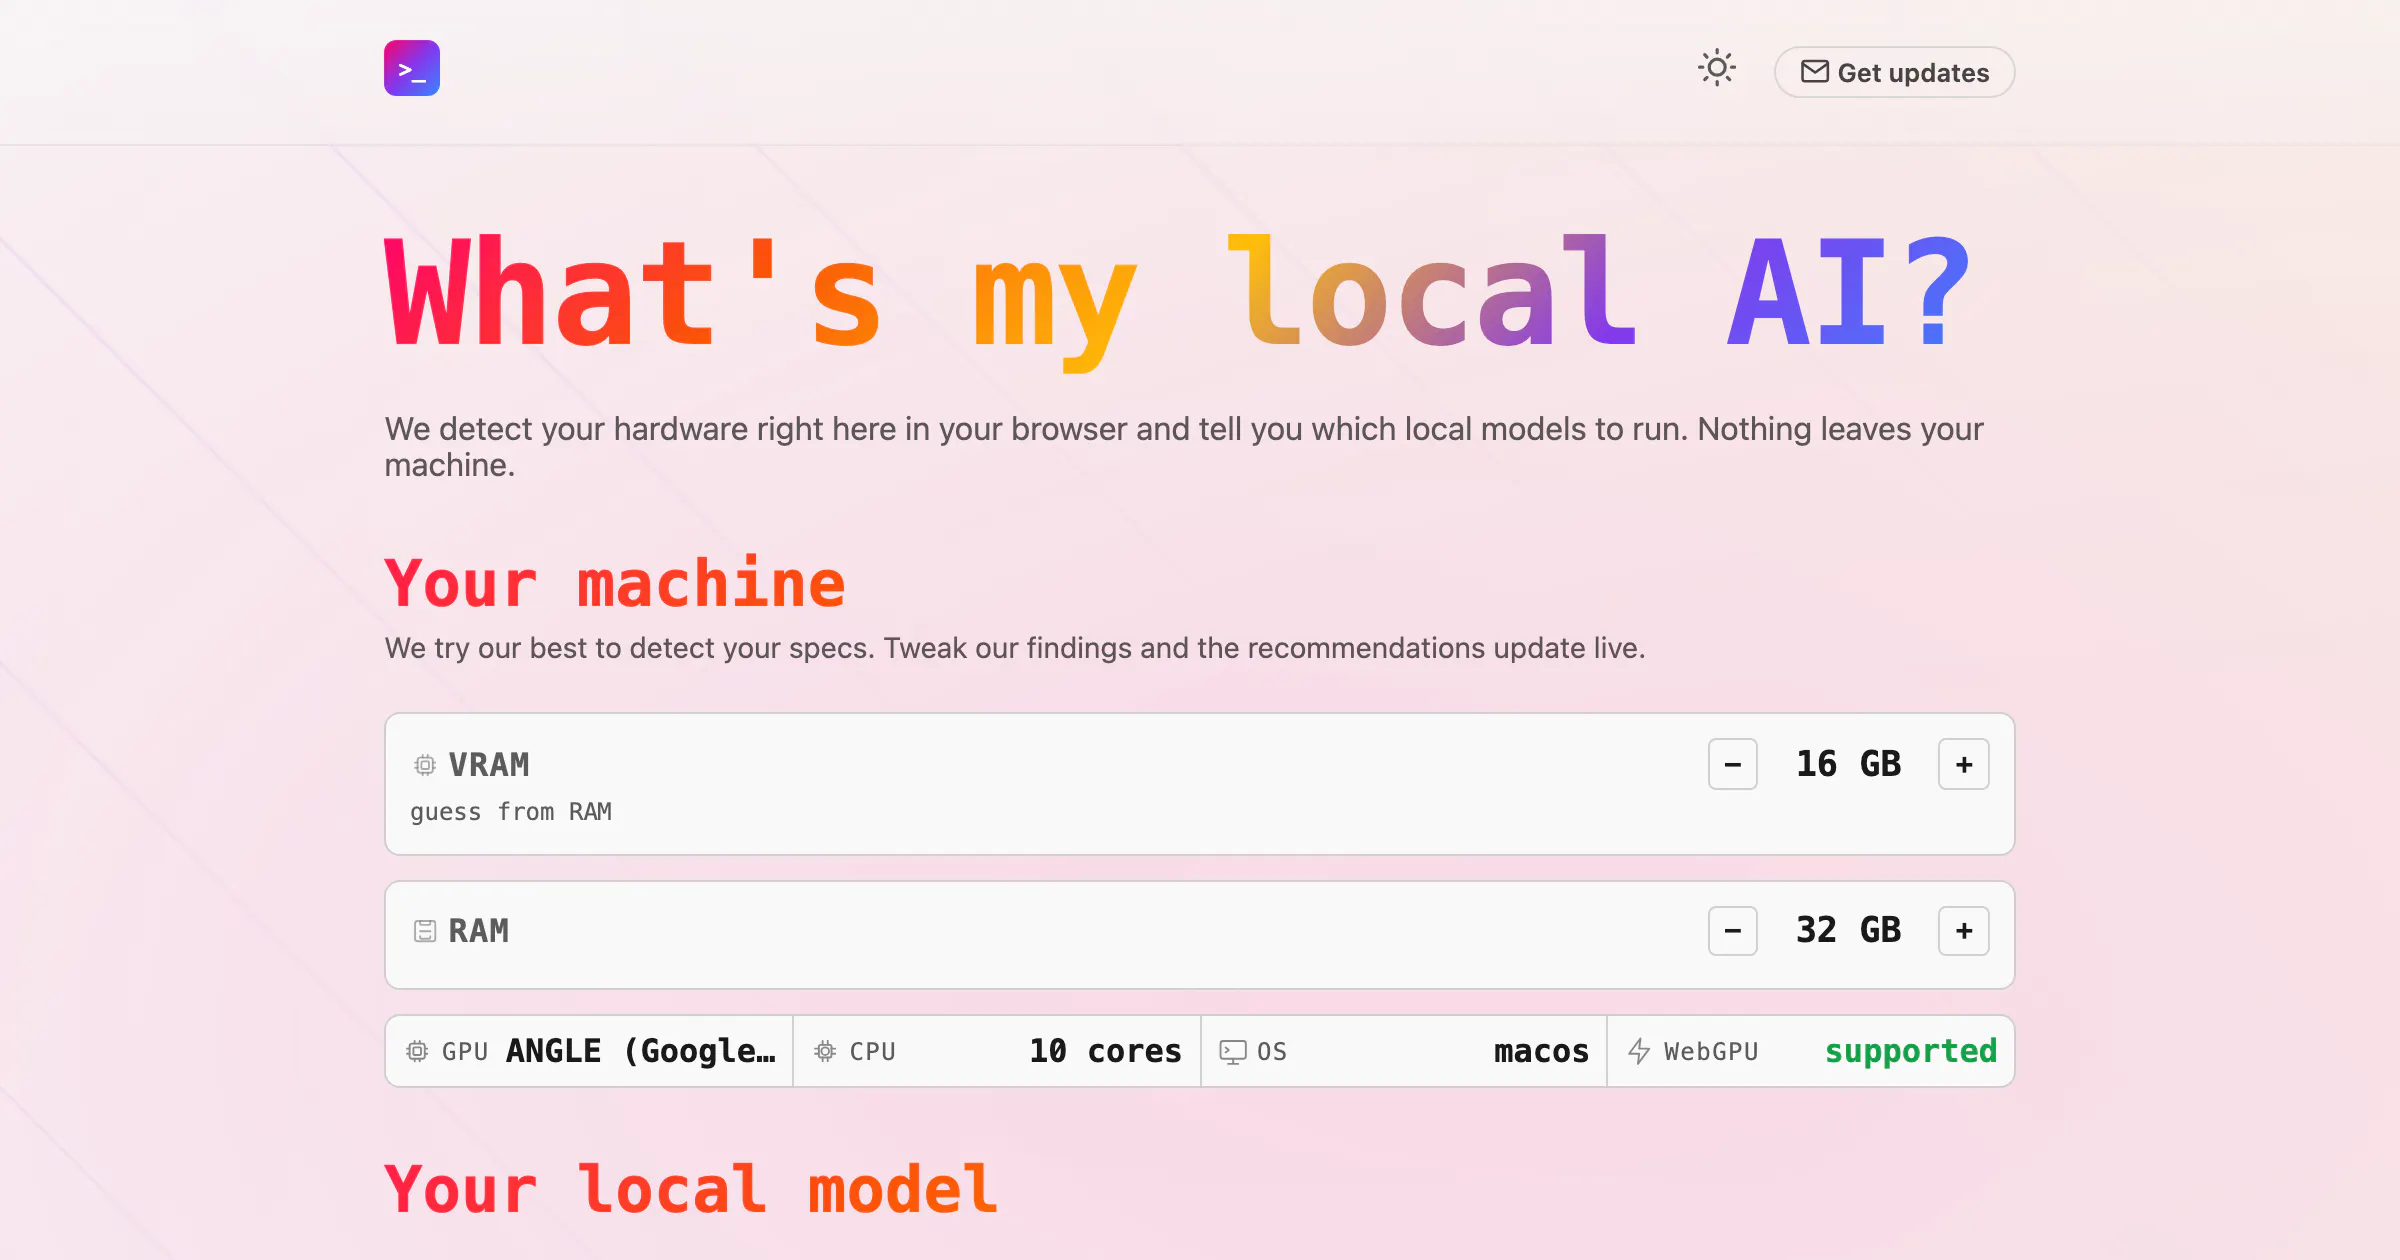
ModelFit helps you choose the best local AI models for your Apple Silicon Mac, iPhone, or NVIDIA GPU. Get Ollama recommendations optimized for your hardware. This tool has been entirely vibecoded using Claude Code and Opus 4.8 / Fable 5. - Data : 850k Google impressions - ~200 organic clicks/day - CLI just passed 1,000 npm downloads (500 in the last week alone) - All organic, zero ad spend.
ModelFit helps you choose the best local AI models for your Apple Silicon Mac, iPhone, or NVIDIA GPU. Get Ollama recommendations optimized for your hardware.
Tell us your hardware and get the single best local LLM it can actually run: one verified pick sized to your exact memory, not a generic chatbot guess. Honest speed and quality estimates for Apple Silicon, iPhone, NVIDIA, and AMD. ModelFit's free, zero-dependency CLI detects your exact hardware, picks the single best local model it can run, and hands you the one-line Ollama command to install it. The dataset behind it is open (CC BY 4.0), and AI agents can query it live over MCP. Gemma 4 is a family, not a model, and its VRAM requirements span a factor of ten. The E2B edge variant loads in 2.3 GB while the 31B dense flagship wants 20 GB. Picking the wrong variant for your hard... GPT-OSS…from modelfit.io
Does a similar job
all alternatives → Getting GLM 5.2 running on my slow computerJul 2026 · github.com · ▲937
A few days ago I found myself trying out GLM 5.2 and was really positively impressed. The capabilities and security I was getting from this LLM are similar to those I've gotten from models like Claude or GPT, and this really surprised me. But then I thought, "I wonder how it would work on a normal computer like mine," and above all, "I wonder if it would work without going into OOM on a computer like mine." So I started working with the help of agents to test this possibility. I started converting the model to int4, understanding MTP usage, and if possible implementing DSA for long context.…
 I made an app to use local AI as daily driver2024 · recurse.chat · ▲637
Hi Hackers, Excited to share a macOS app I've been working on: https://recurse.chat/ for chatting with local AI. While it's amazing that you can run AI models locally quite easily these days (through llama.cpp / llamafile / ollama / llm CLI etc.), I missed feature complete chat interfaces. Tools like LMStudio are super powerful, but there's a learning curve to it. I'd like to hit a middleground of simplicity and customizability for advanced users. Here's what separates RecurseChat out from similar apps: - UX designed for you to use local AI as a daily driver.…
 1CodeJan 2026 · github.com · ▲569
Just to clarify the background a bit. This project wasn’t planned as a big standalone release at first. On January 16, Ollama added support for an Anthropic-compatible API, and I was curious how far this could be pushed in practice. I decided to try plugging local Ollama models directly into a Claude Code-style workflow and see if it would actually work end to end. Here is the release note from Ollama that made this possible: https://ollama.com/blog/claude Technically, what I do is pretty straightforward: - Detect which local models are available in Ollama. - When…

- TFThe fastest way to run Mixtral 8x7B on Apple Silicon Macs2024 · ▲18
I’d originally launched my app: Private LLM[1][2] on HN around 10 months ago, with a single RedPajama Chat 3B model. The app has come a long way since then. About a month ago, I added support for 4-bit OmniQuant quantized Mixtral 8x7B Instruct model, and it seems to outperform Q4 models at inference speed and Q8 models at text generation quality, while consuming only about 24GB of RAM[3] at 8k context length. The trick is: a) to use a better quantization algorithm and b) to use unquantized embeddings and the MoE gates (the overhead is quite small). Other notable features include many more…
More ai this month
the category →


Paintings by AI models: programs run through a simulation of oil paint.
AI · 21d ago · stillwet.art
 PixVerse R2▲381
A real-time world model you can explore and change
AI · 30d ago · world.pixverse.video

Source: Product Hunt launch ↗
Launched alongside, July 2026
the whole month →- IR
I might be the only SRE on Earth with his own bowling center. It's a more in-depth gig than you'd think. My family and I bought an abandoned 8-lane bowling center in the rural mid-west. In our small town there weren't many recreation options for families. You've heard of a food desert? This is an R&R desert. It had been abandoned for a good reason. The roof leaks, the electrical system was constantly surging, and my 70-year-old bowling equipment (still) doesn't work perfectly. The system that keeps your score is particularly interesting to me. It's the thing you watch during your game, but…
Life & fun · Jul 2026

 18 Words▲1,160
Play 18 Words, the free daily word puzzle. The official home is 18words.com. Tap Play now to open today
Life & fun · Jul 2026 · 18words.com
- BA
Over the past few months, our team has been building more and more slidedecks using web frontend technologies with coding harnesses like Claude Code, but a common complaint is to make even small edits we need to edit the code either manually or via the harness. To avoid this loop, I ended up creating Bento, a single HTML file with everything you need in a slide tool including animations and shared editing. There's no install or cloud login, everything works offline. The default deck is around 560 KB and it doesn't need to fetch anything once you got it. Open it in a browser and then you can…
Dev tools · Jul 2026 · bento.page
A few days ago I found myself trying out GLM 5.2 and was really positively impressed. The capabilities and security I was getting from this LLM are similar to those I've gotten from models like Claude or GPT, and this really surprised me. But then I thought, "I wonder how it would work on a normal computer like mine," and above all, "I wonder if it would work without going into OOM on a computer like mine." So I started working with the help of agents to test this possibility. I started converting the model to int4, understanding MTP usage, and if possible implementing DSA for long context.…
AI · Jul 2026 · github.com
 OpenSEO▲928
Hello! For the last 2 months, I've been building OpenSEO. It's a user friendly UI wrapping the DataForSEO API which has high quality SEO data for keywords, backlinks, AI SEO and competitor research. Instead of paying $100+ per month, you buy DataForSEO credits and pay only for usage. The coolest thing about the project so far has been hearing about what people are building on top of it. People are using coding agents to quickly integrate with Google Search Console, Google Ads and building their own AI SEO and reporting features. Many were already building their own custom solutions around…
Dev tools · Jul 2026 · openseo.so