AI · alternatives · 2026

24 alternatives to 30k IKEA items in flat text
OP here. I took the unofficial IKEA US dataset (originally scraped by jeffreyszhou) and converted all 30,511 products into a flat, markdown-like protocol called CommerceTXT. The goal: See if a flatter structure is more efficient for LLM context windows. The results: - Size: 30k products across 632 categories. - Efficiency: The text version uses ~24% fewer tokens (3.6M saved total) compared to the equivalent minified JSON. - Structure: Files are organized in folders (e.g. /products/category/), which helps with testing hierarchical retrieval routers. The link goes to the dataset…
This dataset contains 30,511 IKEA products converted from JSON into CommerceTXT, a flat markdown-like format designed to reduce token usage in large language models. The 3.6 million products span 632 categories… Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes.
- 1

The site hit #1 on HN about a year ago. Got enough traffic that I turned it into a proper API. What's there: - REST API — 35k products, manually filterable by category, free key, 60 req/min - CLI — npx anycrap random -c food - faker.js plugin — bundled, no API call, works offline - HuggingFace dataset — full 35k rows for ML/training https://anycrap.shop/developers
2025 · anycrap.shop · its alternatives →
- 2

Outlines is a Python library that focuses on text generation with large language models. Brandon and I are not LLM experts and started the project a few months ago because we wanted to understand better how the generation process works. Our original background is probabilistic, relational and symbolic programming. Recently we came up with a fast way to generate text that matches a regex (https://blog.normalcomputing.ai/posts/2023-07-27-regex-guide...). The basic idea is simple: regular expressions have an equivalent Deterministic-Finite Automaton (DFA) representation. We…
2023 · github.com · its alternatives →
- 3PT
2024 · adamgrant.info · its alternatives →
- 4

Set of scripts and notebooks used to produce results visible in RecipeNLG paper - Glorf/recipenlg
2020 · github.com · its alternatives →
- 5CA
Hi HN, author here. I built CommerceTXT because I got tired of the fragility of extracting pricing and inventory data from HTML. AI agents currently waste ~8k tokens just to parse a product page, only to hallucinate the price or miss the fact that it's "Out of Stock". CommerceTXT is a strict, read-only text protocol (CC0 Public Domain) designed to give agents deterministic ground truth. Think of it as `robots.txt` + `llms.txt` but structured specifically for transactions. Key technical decisions v1.0: 1. *Fractal Architecture:* Root -> Category -> Product files. Agents only fetch what they…
Dec 2025 · commercetxt.org · its alternatives →
- 6

I've developed a Python API service that uses GPT-4o for OCR on PDFs. It features parallel processing and batch handling for improved performance. Not only does it convert PDF to markdown, but it also describes the images within the PDF using captions like `[Image: This picture shows 4 people waving]`. In testing with NASA's Apollo 17 flight documents, it successfully converted complex, multi-oriented pages into well-structured Markdown. The project is open-source and available on GitHub. Feedback is welcome.
2024 · github.com · its alternatives →
- 7

Built a tool for transforming unstructured data into structured outputs using language models (with 100% adherence). If you're facing problems getting GPT to adhere to a schema (JSON, XML, etc.) or regex, need to bulk process some unstructured data, or generate synthetic data, check it out. We run our own tuned model (you can self-host if you want), so, we're able to have incredibly fine grained control over text generation. Repository: https://github.com/automorphic-ai/trex Playground: https://automorphic.ai/playground
2023 · automorphic.ai · its alternatives →
- 8

Turn any webpage into structured data using LLMs. Contribute to mishushakov/llm-scraper development by creating an account on GitHub.
2024 · github.com · its alternatives →
- 9

We've been building data pipelines that scrape websites and extract structured data for a while now. If you've done this, you know the drill: you write CSS selectors, the site changes its layout, everything breaks at 2am, and you spend your morning rewriting parsers. LLMs seemed like the obvious fix — just throw the HTML at GPT and ask for JSON. Except in practice, it's more painful than that: - Raw HTML is full of nav bars, footers, and tracking junk that eats your token budget. A typical product page is 80% noise. - LLMs return malformed JSON more often than you'd expect, especially with…
Mar 2026 · github.com · its alternatives →
- 10

- 11
 Polydata▲19
Simplify shopify product translations with imports by sku
2024 · polydata.app · its alternatives →
- 12

- 13

Identify items for digital asset and inventory management
2024 · api4.ai · its alternatives →
- 14

Hi HN, I'm proud to show you that I've finally managed to create a Receipt-Image to JSON converter, including line-items! Over the past 10 years, I have periodically tried (every ~3 years or so) to convert Receipt-Images to JSON. What particularly interested me were the line-items. It began with a Bachelor's project where we wanted to track prices by extracting product prices from line items. However, it was not feasible to ask users to type them all into our platform. I quickly realized this process was way too tedious. Only when taking a picture is all that is required, would such a…
2023 · line-items.com · its alternatives →
- 15AT
Hey HN! Erik here from banana.dev We’ve trained a small(ish) language model on structured extraction, and today we’re launching a playground for it at https://anythingtojson.com. Give it a try! This model continues our work on structured generation, following last week’s launch of Fructose[1], a python client for strongly-typed LLM responses. There seem to be two distinct halves of the problem intended to be solved by Fructose and structured generation: 1. the reasoning ability of the model, such as performing chain of thought, creative acts, and natural language tasks. In a way,…
2024 · anythingtojson.com · its alternatives →
- 16

Improved file parsing for LLM’s. Contribute to Filimoa/open-parse development by creating an account on GitHub.
2024 · github.com · its alternatives →
- 17
Predict size from product name for IKEA-like range of goods
2023 · its alternatives →
- 18

Access e-commerce data from 100,000 stores to power embedded shopping experiences in your app.
2025 · developer.searchagora.com · its alternatives →
- 19

Hey HN, I’m the author. I built Misata because existing tools (Faker, Mimesis) are great for random rows but terrible for relational or temporal integrity. I needed to generate data for a dashboard where "Timesheets" must happen after "Project Start Date," and I wanted to define these rules via natural language. How it works: LLM Layer: Uses Groq/Llama-3.3 to parse a "story" into a JSON schema constraint config. Simulation Layer: Uses Vectorized NumPy (no loops) to generate data. It builds a DAG of tables to ensure parent rows exist before child rows (referential integrity).…
Dec 2025 · github.com · its alternatives →
- 20

Hey HN, solo dev here. After years of frustration with how LLMs handle complex documents, especially PDFs with tables, I decided to build a solution myself. My approach uses a Markdown conversion step to preserve the table structure, which seems to work surprisingly well for chunking. This little parser is the first public piece of a much larger, privacy-focused AI platform I'm building. I'm pretty much running on fumes financially, so any feedback, critique, or support is massively appreciated. Happy to answer any questions about the approach!
Nov 2025 · github.com · its alternatives →
- 21
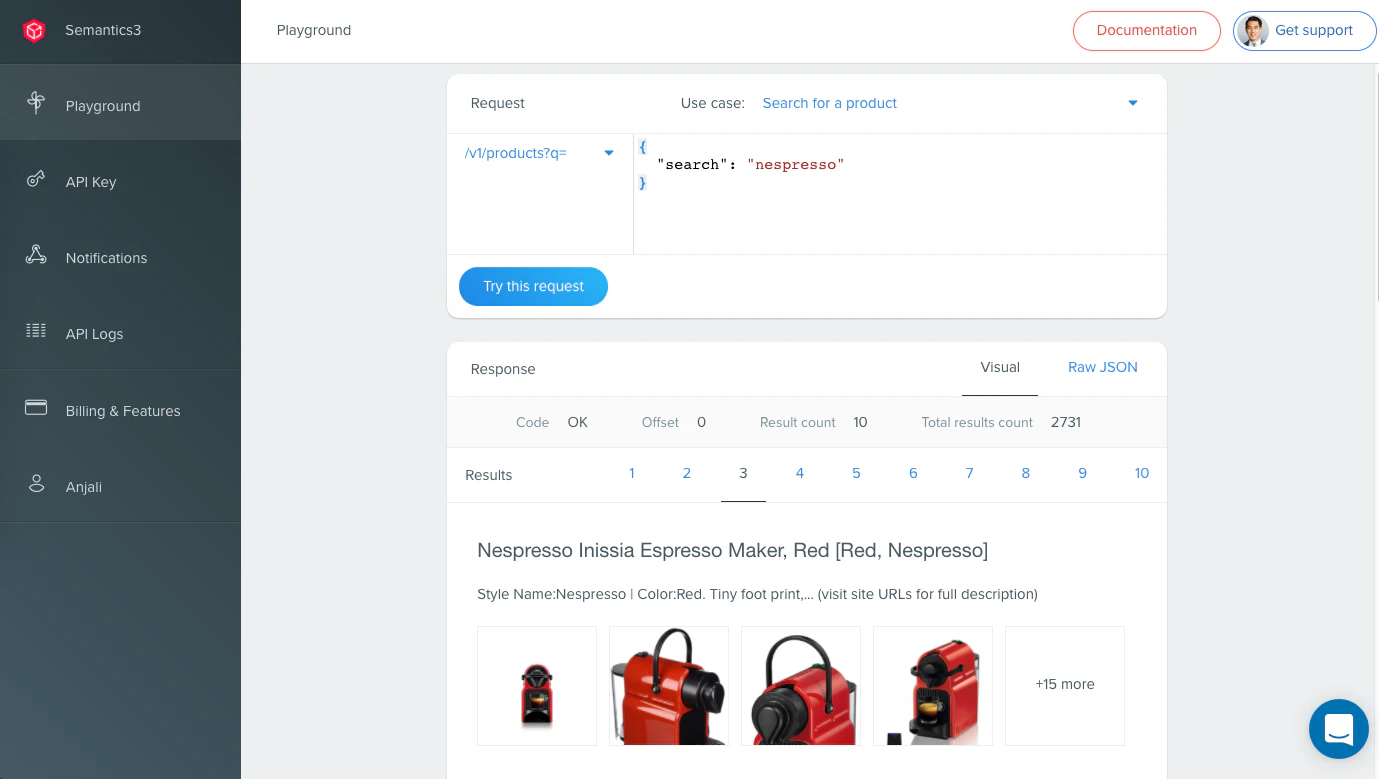
Data needn’t be dry JSON. Visualize product data in RealTime
2017 · its alternatives →
- 22

Over 17k Products and 14k Founders
2023 · exportdata.io · its alternatives →
- 23

Hi HN! I’m working on Agora, an AI search engine for e-commerce products. Excited to launch the Agora API that helps other developers embed shopping experiences into their app. We provide endpoints to search, purchase, and track products sold on 25,000 different Shopify and WooCommerce stores. Early customers are building social shopping apps, marketplaces, and AI shopping assistants. I’d love your feedback!
2025 · developer.searchagora.com · its alternatives →
- 24IU
Hello! I used an LLM to extract structured data from each comment on the “Ask HN: Who is Hiring? (January 2024)” post, available at: https://news.ycombinator.com/item?id=38842977. This created a dataset of 400+ jobs with data such as title, company name, location, is job remote, salary data, and the URL/email to contact. For the UI, a NextJS static site was created to filter and view the structured data.
2024 · hnjobsai.vercel.app · its alternatives →
Also compare
- A store that generates products from anything you type in search alternatives
- LLMs can generate valid JSON 100% of the time alternatives
- Predictive text using only 13kb of JavaScript. no LLM alternatives
- Over 2M cooking recipes ready for text generation alternatives
- CommerceTXT – An open standard for AI shopping context (like llms.txt) alternatives
- PDF to MD by LLMs – Extract Text/Tables/Image Descriptives by GPT4o alternatives
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →