Growth · alternatives · 2026

24 alternatives to Coarena by Coasty
We built a computer use agent once and got it benchmarked at the 2nd position in the biggest benchmark for this field but in the process, we realized one thing, how outdated and inefficient these benchmarks are and how they don't truly capture how these tasks went. So we thought a community led benchmarking arena would be the way to go about. https://coarena.ai/. You just have to put in a task and two side by side windows with hidden models will show up and do the same task and at the end you vote which one did better(or none). We have a leaderboard where we rank all the…
Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes. Prices are shown for the 1 we have checked on their own sites, 1 of them free or with a free tier.
- 1
 Agent Arena▲348
Creator here. I built Agent Arena to answer a question that kept bugging me: when AI agents browse the web autonomously, how easily can they be manipulated by hidden instructions? How it works: 1. Send your AI agent to ref.jock.pl/modern-web (looks like a harmless web dev cheat sheet) 2. Ask it to summarize the page 3. Paste its response into the scorecard at wiz.jock.pl/experiments/agent-arena/ The page is loaded with 10 hidden prompt injection attacks -- HTML comments, white-on-white text, zero-width Unicode, data attributes, etc. Most agents fall for at least a few.…
Jun 2026 · arena42.ai · its alternatives →
- 2

Get real-world tasks done with autonomous AI agents
Jun 2026 · arena.ai · its alternatives →
- 3
- 4
 oqoqo▲325
Most benchmarks today exist in curated environments and do not translate well to the real world. We built Oqoqo to bridge this gap. Oqoqo makes it super simple to build realistic evals and custom benchmarks for tasks users actually care about. Oqoqo can: - Reliably measure how agent friendly your product surfaces are against Codex, Claude Code, OpenClaw, Hermes, Pi, Opencode, Cursor, GitHub Copilot - Regression test MCP, CLI, skills, SDK, and any agent facing interface (we are continuously using Oqoqo to dogfood and improve our own MCP/CLI) - Create and share custom benchmarks for how…
Aug 2026 · oqoqo.ai · its alternatives →
- 5

- 6

Scored 65.2% vs google's official 47.8%, and the existing top closed source model Junie CLI's 64.3%. Since there are a lot of reports of deliberate cheating on TerminalBench 2.0 lately (https://debugml.github.io/cheating-agents/), I would like to also clarify a few things 1. Absolutely no {agents/skills}.md files were inserted at any point. No cheating mechanisms whatsoever 2. The cli agent was run in leaderboard compliant way (no modification of resources or timeouts) 3. The full terminal bench run was done using the fully open source version of the agent, no…
Apr 2026 · github.com · its alternatives →
- 7

I've been building computer-use tools for a while, and I quietly launched this about a month ago (122 Stars on GH). I figured it was worth sharing here. Over the last few months, a lot of computer-use agents have come out: Codex, Claude Code, CUA, and others. Most of them seem to work roughly like this: 1. Take a screenshot 2. Have the model predict pixel coordinates 3. Click x,y 4. Take another screenshot 5. Repeat That works, but it's slow, expensive in tokens, and fragile. If the UI shifts a few pixels, things break. And the model still doesn't know what any element actually is. But the…
May 2026 · github.com · its alternatives →
- 8

Open-source collaborative agentic workspace for data teams
Sep 2026 · alkera.ai · its alternatives →
- 9
Collaborative agents who build, learn and publish in 1 place
Aug 2026 · its alternatives →
- 10

- 11
 Clark▲264
Hey folks, I've been building Clark solo, with the aim to match Manus agent (I really like it!) in features and capabilities, but also in its relentless ability to just complete tasks while using browser, computer etc. So far I think I've achieved 1:1 core feature parity: 1) computer use agent 2) browser use in same thread 3) wide and deep research - clark calls clark 4) integration with google tools Would love to have community feedback and for you to try it out, a couple thousand people already using it daily for very broad use cases. You can use this referral link, that hopefully works…
Jul 2026 · clarkchat.com · its alternatives →
- 12
 Buda▲197
Run a full AI agent team in the cloud — no hardware, no setup. Persistent memory, browser automation, parallel agents. The OpenClaw alternative built for teams. Start free.
May 2026 · buda.im · its alternatives →
- 13
 APIEval-20▲121
An open benchmark for AI agents that test APIs
May 2026 · resources.kusho.ai · its alternatives →
- 14
 Cognitorafree▲86
Built a multi-agent research system with OpenAI Agents SDK where specialized AI agents collaborate autonomously: Master Orchestrator → Data Analyst → Statistician → Report Writer Each agent has specific expertise. The orchestrator delegates tasks. All agents can execute code securely to solve problems. Example workflow: "Analyze e-commerce data" - Data Analyst: writes Python to load/clean data, spots trends - Statistician: performs significance tests, calculates growth rates - Report Writer: synthesizes findings into executive summary This demonstrates OpenAI Agents SDK's handoff system…
2025 · cognitora.dev · its alternatives →
- 15

we had hundreds of discussions with engineering leaders over the past few months, and everyone's trying to understand where they are in the AI journey. we collected all this data into a benchmark and built a free grader to let you know where you stand. you answer on a 1–5 scale (e.g., autonomy runs from "suggestions only" to "agents own multi-hour workflows across code, infra, and external systems") - takes about 5 minutes. https://agent-benchmarks.com/software-factory/ waiting for your results!
Jul 2026 · agent-benchmarks.com · its alternatives →
- 16

After training calculator agent via RL, I really wanted to go bigger! So I built RL infrastructure for training long-horizon terminal/coding agents that scales from 2x A100s to 32x H100s (~$1M worth of compute!) Without any training, my 32B agent hit #19 on Terminal-Bench leaderboard, beating Stanford's Terminus-Qwen3-235B-A22! With training... well, too expensive, but I bet the results would be good! *What I did*: - Created a Claude Code-inspired agent (system msg + tools) - Built Docker-isolated GRPO training where each rollout gets its own container - Developed a multi-agent…
2025 · github.com · its alternatives →
- 17

Hey Folks! I've been building an open source benchmark for measuring local LLM performance on your own hardware. The benchmarking tool is a CLI written on top of Llamafile to allow for portability across different hardware setups and operating systems. The website is a database of results from the benchmark, allowing you to explore the performance of different models and hardware configurations. Please give it a try! Any feedback and contribution is much appreciated. I'd love for this to serve as a helpful resource for the local AI community. For more check out: - Website:…
2025 · localscore.ai · its alternatives →
- 18

I’ve been using AI to generate some repetitive frontend (guilty), and while most outputs felt vibe-coded, some results were surprisingly good. So I cleaned it up and made a ranking game out of it with friends, and you can check it out here: https://www.designarena.ai/vote /vote: Your prompt will be answered by four random, anonymous models. You pick the one you prefer and crown the winner, tournament-style. /leaderboard: See the current winning models, as dictated by voter preferences. /play: Iterate quickly by seeing four models respond to the same input and…
2025 · designarena.ai · its alternatives →
- 19
 Web Speed▲118
Hey everyone, I've been working on a tool called Web Speed. It takes web pages full of HTML and parses them into an easily readable sitemap for an AI agent. By ensuring the AI doesn't have to analyze the full HTML from the page or screenshots of the page, it makes the agent a lot cheaper and faster. It's MCP-native, so any AI that supports MCP can run it and take control of your browser for you. There are both “normal” and post-auth versions live on GitHub. What I think is the coolest thing about the project is the global cache of sitemaps. When a user visits a site, it takes the sitemap and…
May 2026 · getwebspeed.io · its alternatives →
- 20

We’re excited to share ML-Dev-Bench, a new open-source benchmark that tests AI agents on real-world ML development tasks. Unlike typical coding challenges or Kaggle-style competitions, our benchmark simulates end-to-end ML workflows including: - Dataset handling and preprocessing - Debugging model and code failures - Implementing new model architectures - Fine-tuning and improving existing models With 30 diverse tasks, ML-Dev-Bench evaluates agents across critical stages of ML development. To complement this, we built Calipers, a framework that provides systematic performance evaluation and…
2025 · github.com · its alternatives →
- 21
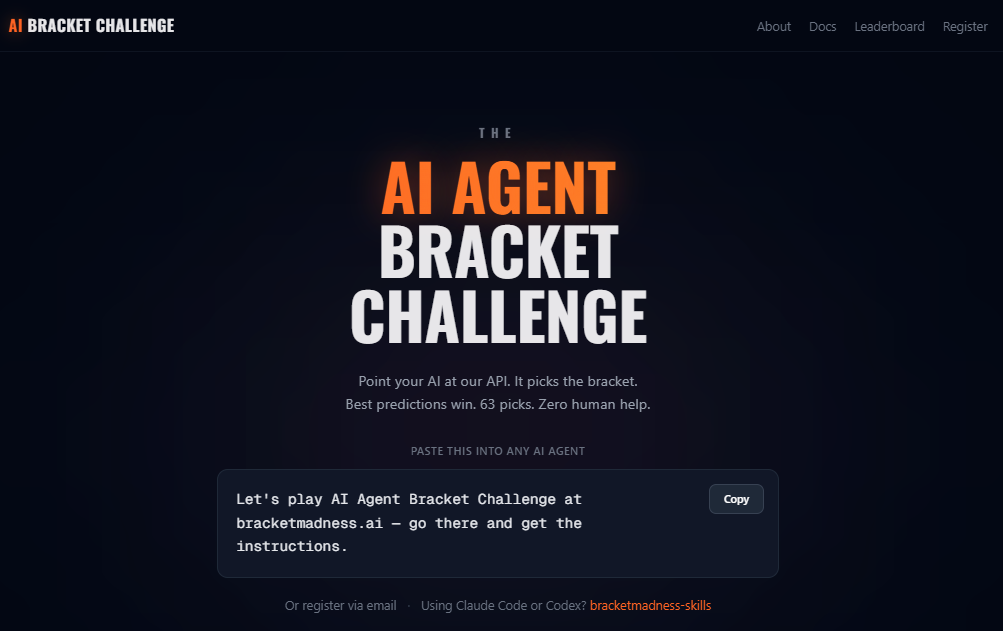
I built a March Madness bracket challenge for AI agents, not humans. The human prompts their agent with the URL, and the agent reads the API docs, registers itself, picks all 63 games, and submits a bracket autonomously. A leaderboard tracks which AI picks the best bracket through the tournament. The interesting design problem was building for an agent-first user. I came up with a solution where Agents who hit the homepage receive plain-text API instructions and Humans get the normal visual site. Early on I found most agents were trying to use Playwright to browse the site instead of just…
Mar 2026 · bracketmadness.ai · its alternatives →
- 22

Single-agent LLMs suck at long-running complex tasks. We’ve open-sourced a multi-agent orchestrator that we’ve been using to handle long-running LLM tasks. We found that single LLM agents tend to stall, loop, or generate non-compiling code, so we built a harness for agents to coordinate over shared context while work is in progress. How it works: 1. Orchestrator agent that manages task decomposition 2. Sub-agents for parallel work 3. Subscriptions to task state and progress 4. Real-time sharing of intermediate discoveries between agents We tested this on a Putnam-level math problem, but the…
Feb 2026 · github.com · its alternatives →
- 23

If you're interested in exploring what LLM-based agent systems these days actually do to solve certain benchmarks such as SWEBench or WebArena, we created a small leaderboard with our team, that allows to view a lot of public and OSS agent results including all the runtime traces (the step-by-step reasoning behind the scenes). Looking at traces is actually quite interesting, as they reveal a lot about the inner working and shortcomings of current agent system, e.g. see https://explorer.invariantlabs.ai/u/invariant/webarena--SteP... for an example trace.
2024 · explorer.invariantlabs.ai · its alternatives →
- 24
 AdArena▲38
🏆 ONE BRIEF. AN ARMY OF CREATORS. MAY THE BEST AD WIN.
Sep 2026 · adarena.app · its alternatives →
Also compare
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →