Dev tools · alternatives · 2026

24 alternatives to PhearJS, render JS webpages to JSON with PhantomJS
PhearJS is an API for PhantomJS. It
PhearJS is an API that renders JavaScript-heavy webpages using PhantomJS and returns the results as structured JSON. It addresses the problem of scraping dynamic sites that rely on AJAX and client-side rendering by… Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes. Prices are shown for the 1 we have checked on their own sites, 1 of them free or with a free tier. PhearJS, render JS webpages to JSON with PhantomJS launched in 2015; newer entries below may have overtaken it.
- 1

- 2
 Turn any website into an API (for those who miss Kimono)free tier, from $19/mo▲332
Web scraping made simple — extract data with our free Chrome extension and powerful cloud platform. Turn websites into structured data at scale, via dashboard or API.
2019 · simplescraper.io · its alternatives →
- 3

Ditch your scraper. Make one API call with any tool.
Jun 2026 · tabstack.ai · its alternatives →
- 4

Hello HN! I became frustrated with the unpredictible/poor match quality and opaqueness of "relevance scores" in existing fuzzy and fulltext search libs, so I tried something different and this is the result. The main selling point is the result quality / ordering, with best-in-class memory overhead and excellent performance being bonuses. The API is pretty stable at this point, but looking for feedback before committing to 1.0. TL;DR The test corpus is a 4MB json file with 162k words/phrases, so give it a second for initial download. You can also drag/drop your own…
2022 · github.com · its alternatives →
- 5
 Simple Scraper▲556
Turn any website into an API in just a few seconds.
2019 · simplescraper.io · its alternatives →
- 6

A complete and versatile web scraper. Contribute to ruipgil/scraperjs development by creating an account on GitHub.
2014 · github.com · its alternatives →
- 7

Hey HN, This is Jan, founder of Apify, a web scraping and automation platform. Drawing on our team's years of experience, today we're launching Crawlee [1], the web scraping and browser automation library for Node.js that's designed for the fastest development and maximum reliability in production. For details, see the short video [2] or read the announcement blog post [3]. Main features: - Supports headless browsers with Playwright or Puppeteer - Supports raw HTTP crawling with Cheerio or JSDOM - Automated parallelization and scaling of crawlers for best performance - Avoids blocking using…
2022 · crawlee.dev · its alternatives →
- 8PJ
2014 · phantomjs-pad.ozaur.com · its alternatives →
- 9
 ManyPI▲354
10x your revenue by finding your ideal customers
Dec 2025 · manypi.com · its alternatives →
- 10

Extract web data into structured JSON, no scraper required.
Jun 2026 · tabstack.ai · its alternatives →
- 11
 Web Scraper API▲287
Scrape the web at scale without getting blocked
2021 · datashake.com · its alternatives →
- 12
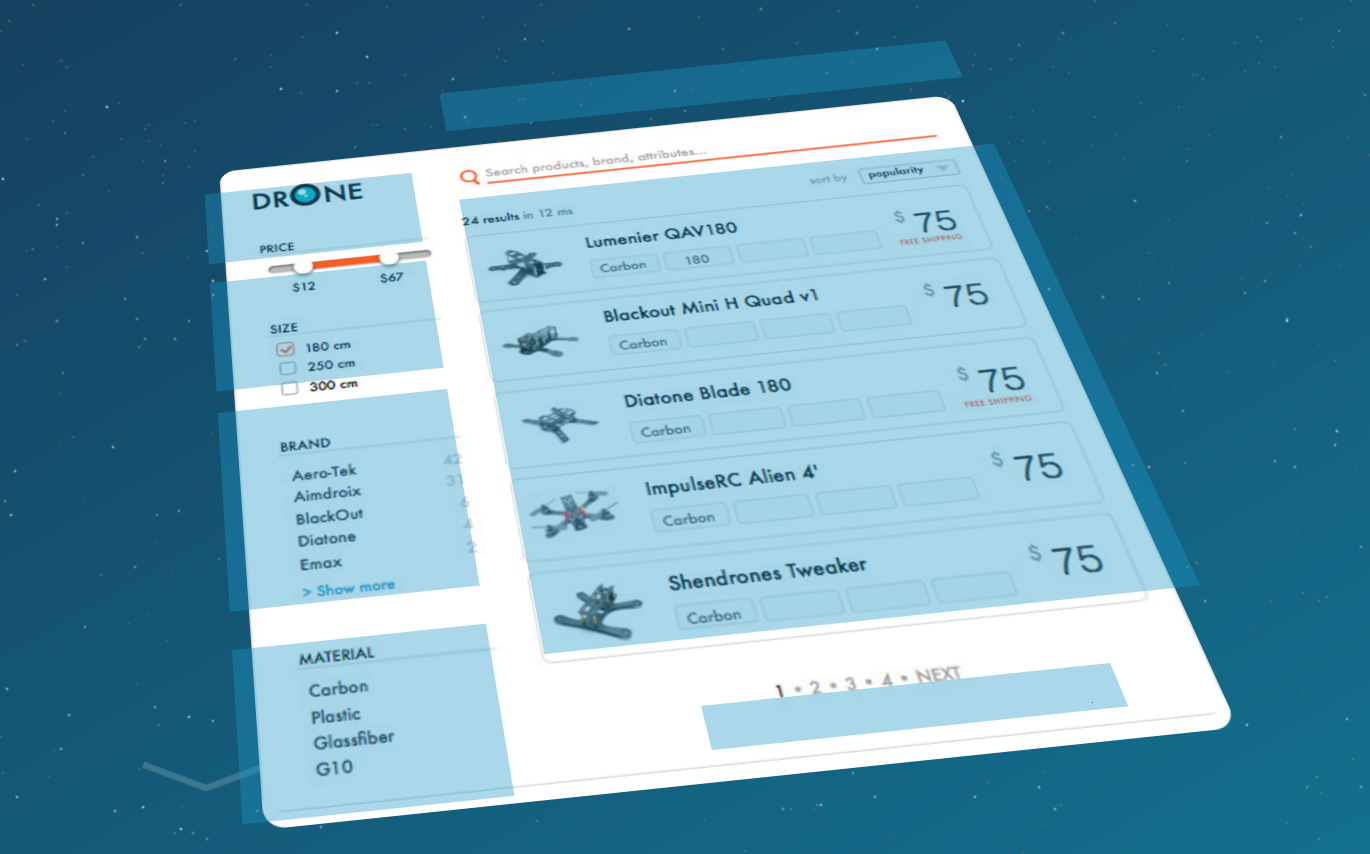
JavaScript UI library for building great search experiences
2015 · community.algolia.com · its alternatives →
- 13

I built µJS because I wanted AJAX navigation without the verbosity of HTMX or the overhead of Turbo. It intercepts links and form submissions, fetches pages via AJAX, and swaps fragments of the DOM. Single tag, one call to `mu.init()`. No build step, no dependencies. Key features: patch mode (update multiple fragments in one request), SSE support, DOM morphing via idiomorph, View Transitions, prefetch on hover, polling, and full HTTP verb support on any element. At ~5KB gzipped, it's smaller than HTMX (16KB) and Turbo (25KB), and works with any backend: PHP, Python, Go, Ruby, whatever.…
Mar 2026 · mujs.org · its alternatives →
- 14

We've been building data pipelines that scrape websites and extract structured data for a while now. If you've done this, you know the drill: you write CSS selectors, the site changes its layout, everything breaks at 2am, and you spend your morning rewriting parsers. LLMs seemed like the obvious fix — just throw the HTML at GPT and ask for JSON. Except in practice, it's more painful than that: - Raw HTML is full of nav bars, footers, and tracking junk that eats your token budget. A typical product page is 80% noise. - LLMs return malformed JSON more often than you'd expect, especially with…
Mar 2026 · github.com · its alternatives →
- 15

SnapSearch is Search Engine Optimisation for Javascript, HTML 5 and Single Page Applications. Make your sites crawlable with SnapSearch. AngularJS SEO, BackboneJS SEO, Ember SEO, jQuery SEO Knockout SEO, Meteor SEO and Sails SEO.
2014 · snapsearch.io · its alternatives →
- 16

Crawlee—A web scraping and browser automation library for Node.js to build reliable crawlers. In JavaScript and TypeScript. Extract data for AI, LLMs, RAG, or GPTs. Download HTML, PDF, JPG, PNG, and other files from websites. Works with Puppeteer, Playwright, Cheerio, JSDOM, and raw HTTP. Both headf
2018 · github.com · its alternatives →
- 17

Pa11y is your automated accessibility testing pal. Contribute to pa11y/pa11y development by creating an account on GitHub.
2015 · github.com · its alternatives →
- 18
- 19
 Feathery.io Free▲100
Host your JS application, now FREE to get started
2019 · app.feathery.io · its alternatives →
- 20
- 21

Learn how to scrape webpages using Puppeteer and Serverless Functions built with OpenFaaS.
2020 · openfaas.com · its alternatives →
- 22

Loads a web page in headless Chrome using Puppeteer and prints it to PDF. The input is a JSON object and output is a PDF file.
2017 · apify.com · its alternatives →
- 23
- 24SR
Searchkit - UI Widgets for Elasticsearch. React, Vue & Javascript supported
2016 · searchkit.co · its alternatives →
Also compare
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →