AI · alternatives · 2026

24 alternatives to Lemonade: Run LLMs Locally with GPU and NPU Acceleration
Lemonade is an open-source SDK and local LLM server focused on making it easy to run and experiment with large language models (LLMs) on your own PC, with special acceleration paths for NPUs (Ryzen™ AI) and GPUs (Strix Halo and Radeon™). Why? There are three qualities needed in a local LLM serving stack, and none of the market leaders (Ollama, LM Studio, or using llama.cpp by itself) deliver all three: 1. Use the best backend for the user’s hardware, even if it means integrating multiple inference engines (llama.cpp, ONNXRuntime, etc.) or custom builds (e.g., llama.cpp with ROCm betas). 2.…
Lemonade is an open-source SDK and local server that runs large language models on personal computers with hardware acceleration for NPUs and GPUs. It integrates multiple inference engines to optimize performance for… Below are 24 products that do a similar job, ranked by how close each is in meaning and then by launch-day votes. Prices are shown for the 1 we have checked on their own sites, 1 of them free or with a free tier.
- 1

Hi HN! I'm just sharing a project I've been working on during the LLM Efficiency Challenge - you can now finetune Llama with QLoRA 5x faster than Huggingface's original implementation on your own local GPU. Some highlights: 1. Manual autograd engine - hand derived backprop steps. 2. QLoRA / LoRA 80% faster, 50% less memory. 3. All kernels written in OpenAI's Triton language. 4. 0% loss in accuracy - no approximation methods - all exact. 5. No change of hardware necessary. Supports NVIDIA GPUs since 2018+. CUDA 7.5+. 6. Flash Attention support via Xformers. 7. Supports 4bit and 16bit…
2023 · github.com · its alternatives →
- 2

I've been playing around with https://github.com/zphang/minimal-llama/ and https://github.com/tloen/alpaca-lora/blob/main/finetune.py, and wanted to create a simple UI where you can just paste text, tweak the parameters, and finetune the model quickly using a modern GPU. To prepare the data, simply separate your text with two blank lines. There's an inference tab, so you can test how the tuned model behaves. This is my first foray into the world of LLM finetuning, Python, Torch, Transformers, LoRA, PEFT, and Gradio. Enjoy!
2023 · github.com · its alternatives →
- 3

Hi HN A few folks and I have been working on this project for a couple weeks now. After previously working on the Docker project for a number of years (both on the container runtime and image registry side), the recent rise in open source language models made us think something similar needed to exist for large language models too. While not exactly the same as running linux containers, running LLMs shares quite a few of the same challenges. There are "base layers" (e.g. models like Llama 2), specific configuration to run correctly (parameters, temperature, context window sizes etc). There's…
2023 · github.com · its alternatives →
- 4

Hey HN, we wanted to share our repo where we fine-tuned Llama 3.1 on Google TPUs. We’re building AI infra to fine-tune and serve LLMs on non-NVIDIA GPUs (TPUs, Trainium, AMD GPUs). The problem: Right now, 90% of LLM workloads run on NVIDIA GPUs, but there are equally powerful and more cost-effective alternatives out there. For example, training and serving Llama 3.1 on Google TPUs is about 30% cheaper than NVIDIA GPUs. But developer tooling for non-NVIDIA chipsets is lacking. We felt this pain ourselves. We initially tried using PyTorch XLA to train Llama 3.1 on TPUs, but it was rough: xla…
2024 · github.com · its alternatives →
- 5WM
Try it out! https://glhf.chat/ Hey HN! We’ve been working for the past few months on a website to let you easily run (almost) any open-source LLM on autoscaling GPU clusters. It’s free for now while we figure out how to price it, but we expect to be cheaper than most GPU offerings since we can run the models multi-tenant. Unlike Together AI, Fireworks, etc, we’ll run any model that the open-source vLLM project supports: we don’t have a hardcoded list. If you want a specific model or finetune, you don’t have to ask us for it: you can just paste the Hugging Face link in and…
2024 · glhf.chat · its alternatives →
- 6

Hi everyone, I'm kinda involved in some retrogaming and with some experiments I ran into the following question: "It would be possible to run transformer models bypassing the cpu/ram, connecting the gpu to the nvme?" This is the result of that question itself and some weekend vibecoding (it has the linked library repository in the readme as well), it seems to work, even on consumer gpus, it should work better on professional ones tho
Feb 2026 · github.com · its alternatives →
- 7

Build your own high performance LLM inference engine in C++ and CUDA - a smaller version of vLLM - jmaczan/tiny-vllm
May 2026 · github.com · its alternatives →
- 8
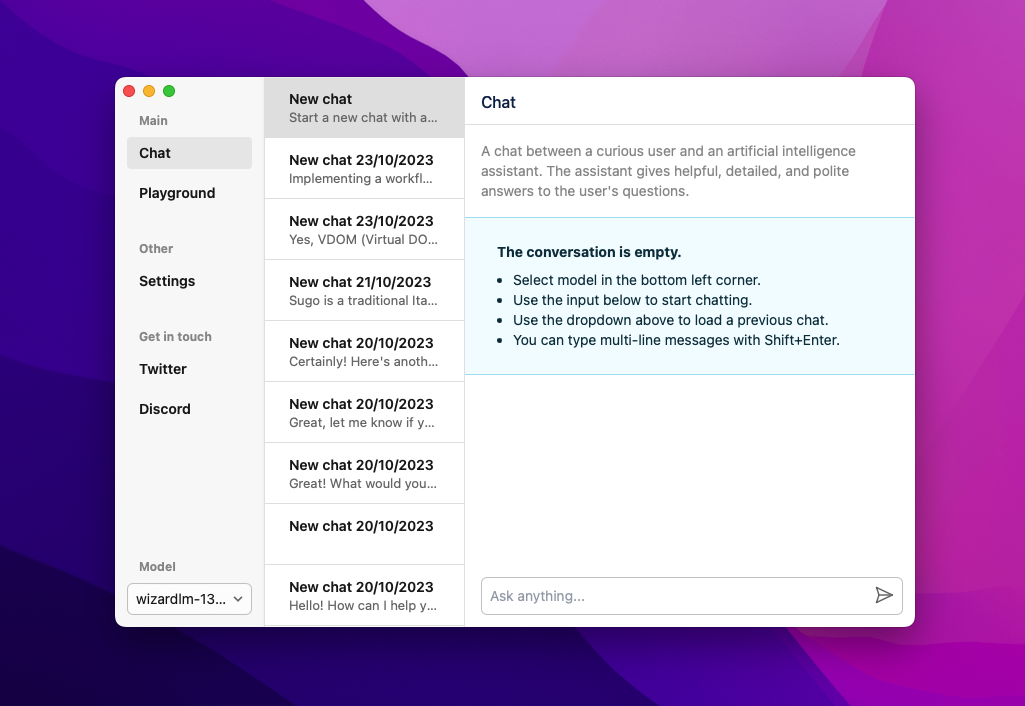
- 9CI
One of the most frequent questions one faces while running LLMs locally is: I have xx RAM and yy GPU, Can I run zz LLM model ? I have vibe coded a simple application to help you with just that. Update: A lot of great feedback for me to improve the app. Thank you all.
2025 · can-i-run-this-llm-blue.vercel.app · its alternatives →
- 10
 LLM Gatewayfree tier▲296
I built an OpenAI-compatible LLM gateway that routes requests to OpenAI, Anthropic, Ollama, vLLM, llama-server, SGLang... anything that speaks /v1/chat/completions. Single Go binary, one YAML config file, no infrastructure. It does the things you'd expect from this kind of gateway... semantic routing via a three-layer cascade (keyword heuristics, embedding similarity, LLM classifier) that picks the best model when clients omit the model field, weighted round-robin load balancing across local inference servers with health checks and failover. The part I think is most…
2025 · llmgateway.io · its alternatives →
- 11

What it is A single 45 MB Windows .exe that embeds llama.cpp and a minimal Tk UI. Copy it (plus any .gguf model) to a flash drive, double-click on any Windows PC, and you’re chatting with an LLM—no admin rights, Cloud, or network. Why I built it Existing “local LLM” GUIs assume you can pip install, pass long CLI flags, or download GBs of extras. I wanted something my less-technical colleagues could run during a client visit by literally plugging in a USB drive. How it works PyInstaller one-file build → bundles Python runtime, llama_cpp_python, and the UI into a single PE. On first launch, it…
2025 · github.com · its alternatives →
- 12
 TensorZero▲307
Hi HN! We're Gabriel & Viraj, and we're excited to open source TensorZero. To be a little cheeky, TensorZero is an open-source platform that helps LLM applications graduate from API wrappers into defensible AI products. 1. Integrate our model gateway 2. Send metrics or feedback 3. Unlock compounding improvements in quality, cost, and latency It enables a data & learning flywheel for LLMs by unifying: • Inference: one API for all LLMs, with <1ms P99 overhead • Observability: inference & feedback → your database • Optimization: better prompts, models, inference strategies • Experimentation:…
2025 · github.com · its alternatives →
- 13
- 14MG
Hello HN, I've been working on this project for a while, and it has been in an "open" beta for some time. I finally believe it's ready for its first release. I hope you like it. Here are some potential questions that may arise: 1. How does it compare to LM Studio? It's likely that if you're already using LM Studio, you'll continue to do so. This project is designed to be more user-friendly. 2. Is it open-source? No, it is not. 3. Does it use any open-source libraries? Yes, it uses llama.cpp and a few others, as indicated in the license information included with the application. 4. Why is not…
2023 · avapls.com · its alternatives →
- 15

G'day, HN! I'm one of the maintainers of `llm`. I've been working alongside a trusty group of contributors to bring this project to life, and we're now at a point where we're ready to share it with the world. Large language models (LLMs) are taking the computing world by storm due to their emergent abilities that allow them to perform a wide variety of tasks, including translation, summarization, code generation, and even some degree of reasoning. However, the ecosystem around LLMs is still in its infancy, and it can be difficult to get started with these models. `llm` is a one-stop shop for…
2023 · github.com · its alternatives →
- 16
 LM Studio▲209
Discover, download, and run local LLMs (incl. DeepSeek R1)
2025 · lmstudio.ai · its alternatives →
- 17

Find the local LLM that actually runs and performs best on your hardware. Ranked by real, recency-aware benchmarks, not parameter count. One command, run it instantly. - Andyyyy64/whichllm
May 2026 · github.com · its alternatives →
- 18AT
I recently built a small open-source tool to benchmark different LLM API endpoints — including OpenAI, Claude, and self-hosted models (like llama.cpp). It runs a configurable number of test requests and reports two key metrics: • First-token latency (ms): How long it takes for the first token to appear • Output speed (tokens/sec): Overall output fluency Demo: https://llmapitest.com/ Code: https://github.com/qjr87/llm-api-test The goal is to provide a simple, visual, and reproducible way to evaluate performance across different LLM providers, including…
2025 · llmapitest.com · its alternatives →
- 19
 NobodyWho▲106
Hey, Hello, we are the team behind NobodyWho; an open-source plugin that embeds large language models functionality inside Unity and Godot games - completely locally and offline. We try to make it as easy and user friendly as possible to use our plugin, so feel free to create an issue on our GitHub if you have any inconveniences - and we will try to improve it! So why might this interest you: - Written in Rust with llama.cpp bindings and optional GPU back-ends (Vulkan / Metal) for fast inference. - Drop-in nodes / components: add a model asset and a chat or embedding node and get a…
Aug 2026 · github.com · its alternatives →
- 20

We wrote our inference engine on Rust, it is faster than llama cpp in all of the use cases. Your feedback is very welcomed. Written from scratch with idea that you can add support of any kernel and platform.
2025 · github.com · its alternatives →
- 21

Calculate token/s & GPU memory requirement for any LLM. Supports llama.cpp/ggml/bnb/QLoRA quantization - RahulSChand/gpu_poor
2023 · github.com · its alternatives →
- 22
 Gradient Bang▲173
Massively multi-player game played by talking to an LLM
May 2026 · gradient-bang.com · its alternatives →
- 23

100% bootstrapped new startup. It lets you fine tune Mistral-7B and SDXL. In particular, for the LLM fine tuning we implemented a dataprep pipeline that turns websites/pdfs/doc files into question-answer pairs for training the small LLM using an big LLM. It includes a GPU scheduler that can do finegrained GPU memory scheduling (Kubernetes can only do whole-GPU, we do it per-GB of GPU memory to pack both inference and fine tuning jobs into the same fleet) to fit model instances into GPU memory to optimally trade off user facing latency with GPU memory utilization It's a pretty…
2023 · docs.helix.ml · its alternatives →
- 24LC
Complete llama.cpp tutorial for 2026. Install, compile with CUDA/Metal, run GGUF models, tune all inference flags, use the API server, speculative decoding, and benchmark your hardware. https://vucense.com/dev-corner/llama-cpp-tutorial-run-gguf-m...
Apr 2026 · its alternatives →
Also compare
- 80% faster, 50% less memory, 0% loss of accuracy Llama finetuning alternatives
- Finetune LLaMA-7B on commodity GPUs using your own text alternatives
- Ollama – Run LLMs on your Mac alternatives
- Tune LLaMa3.1 on Google Cloud TPUs alternatives
- We made glhf.chat – run almost any open-source LLM, including 405B alternatives
- Llama 3.1 70B on a single RTX 3090 via NVMe-to-GPU bypassing the CPU alternatives
Ranked by how close each launch is in meaning, then by votes. Prices were read from each product’s own site when checked and can change. Refine with your own description →